Chapter 11 Big Integers
I am ashamed to tell you
to how many figures I carried these computations,
having no other business at the time.
— Isaac Newton
The main limitation of standard integer types such as int and long is that they have a limited range that is determined by the number of bits they occupy. In the case of int, which uses 32 bits, the range is from \(-2^{31}\) to \(2^{31}-1\), and for long the range is from \(-2^{63}\) to \(2^{63}-1\). This limited numerical range is usually not a problem since most programs only deal with numbers that are fairly small such as array indexes, counters, or file sizes; 64-bit integers in particular provide more than enough headroom in these applications.
But in other applications it is common to operate on much larger quantities. In scientific computing, for instance, we may need to evaluate functions such as factorials and exponentials that quickly outgrow any fixed-width integer type. Similarly, many cryptographic algorithms rely for their security on the use of large integers with hundreds of decimal digits. To distinguish such integers from the “normal” fixed-width integers, integers that can grow arbitrarily large are usually called big integers, bignums, or arbitrary-precision integers. In the remainder of this chapter we will implement two classes that can represent and compute with big integers: BigNat, which operates on nonnegative integers (the natural numbers), and BigInt, which also handles negative integers.
11.1 From Digits to Numbers
Similar to the way we use decimal digits to write down arbitrarily large integers on paper, we can store arbitrarily large integers in memory as arrays of digits — although not necessarily decimal digits. In addition, we compute with such numbers by translating the pen-and-paper methods for adding, multiplying, and dividing decimal numbers into proper algorithms that operate on arrays of digits.
Before we turn to the technical details, let us quickly review the basics of decimal numbers and other positional number systems. A decimal number is a sequence of digits between 0 and 9 in which the position of a digit determines its contribution to the number’s magnitude. In the case of the decimal number 362 880, for instance, the following decimal expansion relates the six decimal digits to the value of the number as a whole:
\(\seteqnumber{0}{11.}{0}\)\begin{align*} 362\,880 &= 3\cdot 100\,000 + 6\cdot 10\,000 + 2\cdot 1000 + 8\cdot 100 + 8\cdot 10 + 0\cdot 1 \end{align*} The position of each digit determines which power of \(10\) it is paired with in the decimal expansion: The rightmost digit is paired with \(10^0=1\), the second digit from the right is paired with \(10^1=10\), and so on. The number 10 in this case is called the base or radix of the number system.
More generally, the value of a number with decimal digits \(d_{n-1}\dots d_0\) is
\(\seteqnumber{0}{11.}{0}\)\begin{equation} \label {eq:decimalexp} (d_{n-1}\ldots d_1d_0)_{10}=d_{n-1}\cdot 10^{n-1} + \dots + d_0\cdot 10^0 = \sum _{k=0}^{n-1} d_k 10^k. \end{equation}
Digits are conventionally numbered from right to left, starting with the index 0, because this ensures that the \(k\)th digit \(d_k\) is multiplied by \(10^k\) in the decimal expansion. Other positional number systems are obtained by using another base instead of 10. In general, given a base \(B>1\), we can expand every integer in the form
\(\seteqnumber{0}{11.}{1}\)\begin{equation} \label {eq:baseexp} (d_{n-1}\ldots d_1d_0)_{B}=d_{n-1}\cdot B^{n-1} + \dots + d_0\cdot B^0 = \sum _{k=0}^{n-1} d_k B^k, \end{equation}
where each digit \(d_k\) is a number between 0 and \(B-1\) inclusive. We already discussed binary numbers (\(B=2\)) and hexadecimal numbers (\(B=16\)) in previous chapters.
In theory, we can represent every integer using every radix \(B\ge 2\), but when it comes to implementing big integers on a computer, some values of \(B\) are more suitable than others. On most modern computers a good choice for the radix is \(B=2^{31}\). This base has the following advantages:
-
• Each digit is a number between 0 and \(2^{31}-1\) and fits exactly in a signed 32-bit integer.
-
• Since \(B\) is a power of 2, we can replace common operations such as multiplication by \(B\) or computing remainders modulo \(B\) with bit operations.
-
• The sum of two digits is at most \(2(B-1)=2^{32}-2\), and their product is at most \((B-1)^2=2^{62}-2^{31}+1\). All arithmetic operations on digits can therefore be performed easily using 64-bit integers.
This is the base we will use for our implementation of big integers.
To familiarize ourselves us with the idea of base-\(2^{31}\) numbers, let’s take a look at an example. In 1938, the astrophysicist Arthur Eddington conjectured that there are exactly \(136\cdot 2^{256}\) protons in the observable universe. Writing this number in base-10 requires 80 digits:
\(\seteqnumber{0}{11.}{2}\)\begin{align*} &15\,747\,724\,136\,275\,002\,577\,605\,653\,961\,181\,555\,468\,044\,717\,914\,527\hookleftarrow \\ &\qquad 116\,709\,366\,231\,425\,076\,185\,631\,031\,296. \end{align*} Written in base-\(2^{31}\), however, nine digits are sufficient. To see this, we first note that we can trivially obtain its base-\(B\) expansion of \(N_E\) by rewriting it as
\(\seteqnumber{0}{11.}{2}\)\begin{equation*} N_E=136\cdot 2^{8+31\cdot 8}=(136\cdot 2^8)\cdot B^8. \end{equation*}
The most significant digit is therefore \(136\cdot 256=34\,816\) and the eight least significant digits are all 0. We therefore have
\(\seteqnumber{0}{11.}{2}\)\begin{equation*} N_E = (34\,816, 0, 0, 0, 0, 0, 0, 0, 0)_{B}. \end{equation*}
Decimal numbers are conventionally written from left to right, starting with the most significant digit and ending with the least significant digit. In computer science, this ordering of digits is called big-endian order since the “big end” of the number — the digit with the biggest impact on the number’s numerical value — comes first. The opposite order is known as little-endian order and starts with the least significant digit. Here is how we would store the base-\(2^{31}\) representation of Eddington’s number in these two formats:
int[] bigEndian = {34816, 0, 0, 0, 0, 0, 0, 0, 0};
int[] littleEndian = {0, 0, 0, 0, 0, 0, 0, 0, 34816};
Even though both representations are equivalent, there are two reasons why little-endian order is usually the better choice for implementing big integers. One reason is that mathematicians number digits from right to left \(d_n\dots d_1d_0\), so little-endian order ensures that the digit \(d_k\) is stored in the \(k\)th field of the array, which makes it easier to translate mathematical formulas into computer programs. The second reason is that many arithmetic algorithms process digits starting with the least significant digit, so little-endian order leads to slightly simpler loops and index computations.
The terms big-endian and little-endian are also used to describe the memory layout of other kinds of data that is broken into multiple smaller pieces. For example, when transmitting a 32-bit value such as 0xf00dcafe over a network connection or writing it to a file, we must decide whether to send the big-endian byte sequence “f0 0d ca fe” or the little-endian byte sequence “fe ca 0d f0”. In the context of file formats and network protocols, the terms byte order and endianness are often used interchangeably.
In the following we will implement a class BigNat that represents arbitrarily large natural numbers in base-\(2^{31}\). The outline of this class is shown in Listing 11.1. We will use a simple array of ints to store the digits in little-endian order. To simplify the implementation of some of the more advanced algorithms discussed later in this chapter, we define two additional fields offset and size that let us specify where in the array the digits are stored: offset is the index of the first digit and size the number of digits starting at that location. For instance, the nine-digit number \(d_{8}\cdots d_1d_0\) can be stored anywhere inside a sufficiently large array:
The other array entries, indicated in gray, are ignored by all methods of BigNat. We will explain the significance of the Comparable interface used in Listing 11.1 in the following section.
Listing 11.1ch11 / BigNat
// A class for representing nonnegative big integers.
public class BigNat
        implements Comparable<BigNat> {
    private final int[] digits;  // array of digits
    private final int offset;    // offset of the first digit
    private final int size;      // number of significant digits

    // ...
}
JDK: Comparable
Listing 11.2 defines two methods for accessing individual digits. The first is digit(), which takes an index between 0 for the least significant and size - 1 for the most significant digit and returns the corresponding digit from the digits array; the position inside the array is computed by adding offset. The second method is digitOr0(), which either returns the digit at a particular index or 0 for positions beyond the most significant digit. In effect, this method extends the array of digits with an infinite number of zeros, similar to the way we can extend decimal numbers by writing additional zeros to the left of the most significant decimal.
Listing 11.2ch11 / BigNat
private int digit(int index) {
    assert index >= 0 && index < size;
    return digits[offset + index];
}

private int digitOr0(int index) {
    assert index >= 0;
    return index < size ? digits[offset + index] : 0;
}
In Listing 11.3 we define two constructors for BigNat. The main constructor takes as its arguments an array of digits, the offset of the first digit from the start of the array, and the number of digits size. The first two parameters are stored unchanged in their respective fields, but size is adjusted to exclude all excess zeros in the most significant digits. This ensures that size always equals the number of significant digits, which has two main benefits:
-
• Two BigNats with the same numerical value always have the same size. As we will discuss shortly, this makes it easier and faster to compare two numbers.
-
• It speeds up most arithmetic operations since redundant zero digits need not be handled.
The second constructor is provided mainly for convenience and creates a new BigNat from all digits in a given array.
Listing 11.3ch11 / BigNat
// Create big integer from a subarray of digits.
private BigNat(int[] digits, int offset, int size) {
    while (size > 0 && digits[offset + size - 1] == 0)
        size--;
    this.digits = digits;
    this.offset = offset;
    this.size = size;
}

// Create big integer from an array of digits.
private BigNat(int[] digits) {
    this(digits, 0, digits.length);
}
Next, we need two functions for comparing and hashing big integers (Listing 11.4). The equals() method tests whether two BigNats have the same size and the same digits; we use the Arrays.equals() method to compare the correct sub-arrays of the two digits fields. To compute the hash code, hashCode() uses the same hash function we also used to speed up LZ77 compression in Section 10.3.
Listing 11.4ch11 / BigNat
public boolean equals(Object o) {
    return (o instanceof BigNat y) && size == y.size
            && Arrays.equals(digits, offset, offset + size,
            y.digits, y.offset, y.offset + y.size);
}

public int hashCode() {
    int hashCode = 1;
    for (int i = offset; i < offset + size; i++)
        hashCode = 31 * hashCode + digits[i];
    return hashCode;
}
Box 11.1: Immutable Classes BigNat is an example of an immutable class, a class whose objects cannot be modified after the constructor has completed. All members of BigNat are declared as final, so they can only be changed in the constructor. In addition, the methods of BigNat don’t modify the contents of the digits array. Every BigNat therefore represents exactly one natural number. Immutable classes have many benefits:
-
• They prevent common programming mistakes. Immutable objects can be freely used in any expression, passed to functions, or stored in data structures without the risk of accidental modification.
-
• They often save memory. It’s rarely necessary to create copies of immutable objects, and multiple instances can share the same internal representation, in this case the digits array.
-
• They can be shared across threads. Although we will not discuss multi-threaded programming in this book, it’s worth mentioning that immutable objects can be accessed safely from multiple threads without the need for manual synchronization.
The main drawback of immutable classes is that they don’t work well with iterative algorithms that repeatedly update the same data. With mutable data structures, we can usually perform these updates “in-place”, by modifying or overwriting the existing data. With immutable data structures, on the other hand, we have to create a new instance for every update, which is often slower and requires more memory. In the case of BigNat, an example of one such an iterative algorithm is the division procedure we will discuss in Section 11.6.
Exercises
[11.1]The constructor of BigNat in Listing 11.3 normalizes numbers by throwing away unnecessary zero digits. Explain how the implementation of equals() must be changed if we omit this normalization step.
11.2 Comparison and Conversion
We just saw how to compare big integers for equality; but what about the remaining comparison operators \(<\), \(\le \), \(\ge \), and \(>\)? In Java, these operators are implemented using the Comparable interface, which defines a single method compareTo():
interface Comparable<T> {
    int compareTo(T value);
}
The compareTo() method implements a so-called three-way comparison, which means that combines the operators \(<\), \(=\), and \(>\) into a single operation. The return value is an integer that indicates how this is related to value:
-
• If \(\mathtt {this} < \mathtt {value}\) the return value is \(<0\).
-
• If \(\mathtt {this} = \mathtt {value}\) the return value is 0.
-
• If \(\mathtt {this} > \mathtt {value}\) the return value is \(>0\).
Similarly, the operators \(\le \) and \(\ge \) correspond to a return value that is \(\le 0\) or \(\ge 0\).
The easiest way to implement a three-way comparison of two numbers and is to compute their difference and return the sign of the result. (This follows directly from the definition above.) But for big integers we can usually determine the proper return value much more quickly. First, if the two numbers differ in length, we immediately know that the numbers with more digits is the larger of the two. And if the two numbers have the same length, we can often find the larger one by comparing only the first few digits. For instance, 8451 is obviously larger than 849 because it has one more digit, and we only need to examine the first two digits to establish that 8451 is smaller than 8591.
This leads us to the implementation of compareTo() shown in Listing 11.5, which first compares size and then the digits themselves. If the two big integers differ in length, we perform a three-way comparison of their size fields using Integer.compare() and return the result. Otherwise, we use a for loop to iterate over the digits, from most to least significant, to find the first pair that differs. These two digits are again compared using Integer.compare(). The last line in compareTo() is only reached if both numbers have the same length and if all digits are equal. In this case the numbers are equal and we return 0.
Listing 11.5ch11 / BigNat
public int compareTo(BigNat v) {
    if (size != v.size)
        return Integer.compare(size, v.size);
    for (int i = size - 1; i >= 0; i--) {
        int ui = digit(i), vi = v.digit(i);
        if (ui != vi)
            return Integer.compare(ui, vi);
    }
    return 0;
}
The methods we have implemented so far are independent of the number system’s base and treat the digits as a plain array of integers, but most of the remaining operations on big integers need to take the radix into account. Listing 11.6 defines three constants that will simplify the task of working with base-\(2^{31}\) digits. The first is BASE, which simply holds the radix \(2^{31}\). Since this number is too large for a regular int, we define the variable as a long integer and compute its value using a bit shift. The second constant is DIGIT_BITS, which holds the number of bits required to store each digit, in our case 31. And the last constant DIGIT_MASK is a bit mask that selects the lowest 31 bits of a long integer. We use this bit mask mainly to replace the remainder operation x % BASE with the faster bit operation x & DIGIT_MASK.1
Listing 11.6ch11 / BigNat
static final long BASE = 1L << 31;
static final int DIGIT_BITS = 31;
static final long DIGIT_MASK = 0x7fffffff;
To see these constants in action, recall the fundamental relationship between a number \(N\) and its digits \(d_n,\dots ,d_0\):
\(\seteqnumber{0}{11.}{2}\)\begin{align*} N = d_{n}\cdot \mathtt {BASE}^{n} + d_{n-1}\cdot \mathtt {BASE}^{n-1} + \cdots + d_{0}\cdot \mathtt {BASE}^0 \end{align*} Since BASE is a power of \(2\), we can rewrite this formula using bit shifts instead of multiplications, which gives us
\(\seteqnumber{0}{11.}{2}\)\begin{align*} N &= (d_{n}\shl \mathtt {DIGIT\_BITS}\cdot n)\\ &\qquad + (d_{n-1}\shl \mathtt {DIGIT\_BITS}\cdot (n-1))\\ &\qquad + \cdots \\ &\qquad + (d_{0}\shl 0). \end{align*} What this formula tells us is that the binary representation of \(N\) can be constructed by concatenating all \(31\)-bit digits into one long string of bits. Conversely, if we know the binary representation of \(N\), we can compute the base-\(2^{31}\) digits by splitting the number into \(31\)-bit chunks. The \(k\)th digit can be obtained by shifting \(N\)’s bits \(k\cdot \mathtt {DIGIT\_BITS}\) bits to the right and isolating the lowest 31 bits:
\(\seteqnumber{0}{11.}{2}\)\begin{equation*} d_k = (N\shr k\cdot \mathtt {DIGIT\_BITS}) \AND \mathtt {DIGIT\_MASK}. \end{equation*}
A simple application of this idea is the factory method fromUnsignedLong() shown in Listing 11.7, which constructs a BigNat from a given 64-bit integer by splitting it into three parts of 31 bits each. This method is primarily useful for constructing small integers such as the three constants ZERO, ONE, and TEN shown in the same listing. With these constants, code that needs to refer to the number 0 can simply use BigNat.ZERO without having to construct a new instance of BigNat. Notice that it is safe to define these numbers as public constants only because BigNat is immutable and their values cannot be changed by other parts of the program.
Listing 11.7ch11 / BigNat
// Create a new instance from the bit pattern of 'v'.
public static BigNat fromUnsignedLong(long v) {
    return new BigNat(new int[]{
            (int) (v & DIGIT_MASK),
            (int) ((v >>> DIGIT_BITS) & DIGIT_MASK),
            (int) ((v >>> 2 * DIGIT_BITS) & DIGIT_MASK)
    });
}

public static final BigNat
        ZERO = fromUnsignedLong(0),
        ONE = fromUnsignedLong(1),
        TEN = fromUnsignedLong(10);
For the opposite conversion, from big integers to integers of type long, we take three digits and reassemble them into a 64-bit integer (Listing 11.8). The toUnsignedLong() method doesn’t check whether the result fits into a long integer and simply returns the number’s lowest 64 bits; this mirrors the way type casts, say, from long to int, work in Java. We will discuss a similar method with appropriate error handling when we discuss signed big integers in Section 11.8.
Listing 11.8ch11 / BigNat
// Return the lowest 64 bits of the big integer.
public long toUnsignedLong() {
    return ((long) digitOr0(2) << 2 * DIGIT_BITS)
            | ((long) digitOr0(1) << DIGIT_BITS)
            | (long) digitOr0(0);
}
1 We discussed this technique in Section 5.3.
11.3 Addition and Subtraction
We can now turn to the problem of implementing the four basic arithmetic operations addition, subtraction, multiplication, and division. The algorithms for these operations resemble the familiar pen-and-paper methods for decimal arithmetic and mainly differ in the radix being used and in the way digits are stored and handled.
To compute the sum of two positive decimal numbers, say \(x=278\) and \(y=124\), we can proceed as follows. Start with the two rightmost digits and compute their sum \(8+4=12\). Write down the trailing digit \(2\) as the last digit of \(x+y\) and remember the leading digit 1 as a carry. This carry is included when adding the next pair of digits, \(7\) and \(2\), which gives us \(7 + 2 + 1=10\); again, write down the trailing digit 0 and set the carry to 1. Continue in this way until all digits have been added:
| 2 | 7 | 8 | \(x\) | ||
| \(+\) | 1 | 2 | 4 | \(y\) | |
| \(+\) | 0 | 1 | 1 | 0 | carry term |
| 0 | 4 | 0 | 2 | \(x+y\) |
The final value of the carry term is written down as the most significant digit of the result.
Even though the algorithm is traditionally taught using decimal numbers, it works almost identically in other number systems. Assume the numbers to be added are \(x=(x_{n-1} x_{n-2}\dots x_0)_B\) and \(y=(y_{n-1} y_{n-2}\dots y_0)_B\) to some base \(B\) and that both numbers have the same number of digits. (If one number has more digits, we simply extend the shorter one with additional zeros.) To find the least significant digit of the sum \(x+y\), we first add the corresponding digits \(t=x_0+y_0\). As with decimal numbers, we write down the lower digit \(t \bmod B\) as the next digit and remember the upper digit \(\lfloor t / B\rfloor \) as a carry \(c\), which is carried over to the next digit. The remaining digits are handled in the same way, except that the carry is included in the sum of digits \(x_k+y_k+c\). A formal description of this method is shown in Algorithm 11.1. The sum of two \(n\)-digit numbers satisfies \(x+y<2B^n\le B^{n+1}\), so the result of the addition algorithm always fits into \(n+1\) digits.
Algorithm 11.1
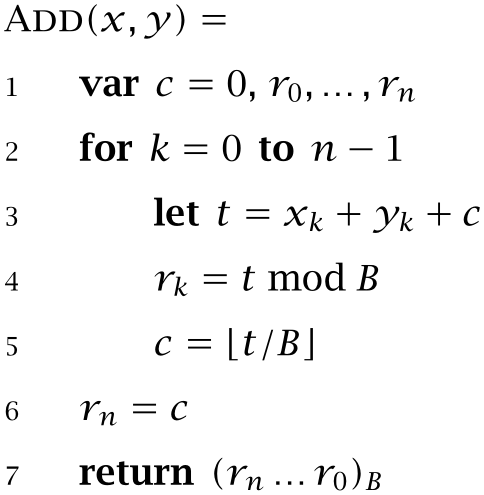
The plus() method in Listing 11.9 implements this algorithm for BigNats. We first allocate a new array for the digits of the result; its size is determined by the larger of the two numbers being added. We then compute each digit of the result, starting with the least significant digit. First, we compute \(r_k\) by adding pairs of digits and the carry and then store the remainder \(r_k\bmod B\) as the next digit in result[] and the quotient \(\lfloor r_k/B\rfloor \) as the carry for the next iteration. Since \(B=2^{31}\) is a power of 2, we can compute the quotient and the remainder using bit operations.
Listing 11.9ch11 / BigNat
// Add two big integers.
public BigNat plus(BigNat y) {
    int[] result = new int[Math.max(size, y.size) + 1];
    int carry = 0;
    for (int i = 0; i < result.length; i++) {
        int tmp = digitOr0(i) + y.digitOr0(i)
                + carry;  // can overflow
        result[i] = tmp & (int) DIGIT_MASK;
        carry = tmp >>> DIGIT_BITS;
    }
    return new BigNat(result);
}
Alert readers may be wondering whether it is safe to define tmp as an int in Listing 11.9, considering that the sum of two digits and the carry can be as large as
\(\seteqnumber{0}{11.}{2}\)\begin{equation*} (2^{31}-1) + (2^{31}-1) + 1 = 2^{32} - 1, \end{equation*}
which does not fit into a signed 32-bit integer. This is a valid concern, and in programming languages that handle integer overflow more strictly, it may be necessary to perform the computation using 64-bit arithmetic. In Java, however, everything works out correctly since arithmetic operations are guaranteed to return the 32 lowest bits of the correct result — and 32 bits is all we need in this case, even if barely. Since we treat tmp as an unsigned quantity, we have to use an unsigned shift ‘>>>’ to compute carry.
What happens if we use ordinary arithmetic operations instead of bit operations to compute the remainder and the carry in Listing 11.9? In this case, we run into problems if the computation of tmp overflows:
int tmp = digitOr0(i) + y.digitOr0(i) + carry;  // can overflow
result[i] = tmp % base;  // WRONG if tmp overflows
carry = tmp / base;  // WRONG  if tmp overflows
In the case of an overflow, the division and remainder operators interpret tmp as a negative number and therefore produce negative results. In Java, the correct solution is to perform the computations using 64-bit integers:
long tmp = digitOr0(i) + y.digitOr0(i) + carry;
result[i] = (int)(tmp % base);
carry = (int)(tmp / base);
Subtraction
A similar method is used to subtract two unsigned numbers. Again, the digits of the result are computed one by one, by subtracting individual digits. Similar to the way the addition algorithm uses a carry term if the sum of two digits is too large, the subtraction algorithm uses a borrow term if the difference of two digits is too small: If the difference \(x_k-y_k\) of two digits is negative, we borrow one unit from the next digit and instead compute \((B+x_k)-y_k\) for this digit and \(x_{k+1}-y_{k+1}-1\) for the next digit.
Let’s compute the difference of \(x=228\) and \(y=174\). We write the two numbers with their digits aligned below each other and add a third row for the borrow terms:
| 2 | 2 | 8 | \(x\) | |
| \(-\) | 1 | 7 | 4 | \(y\) |
| \(-\) | 1 | 0 | 0 | borrow term |
| 0 | 5 | 4 | \(x-y\) |
The rightmost digit of the result is obtained by subtracting the rightmost digits of \(x\) and \(y\), which gives us \(8-4=4\). The result of subtracting the next two digits is \(2-7=-5\), which is negative. In this case, we obtain the correct result by adding 10. This is analogous to “borrowing” one unit from the next digit of \(x\) and computing \(12-7\) instead of \(2-7\); to compensate, we set the borrow term for the next digit to 1. The final digit of \(x-y\) is obtained by subtracting the final digit of \(y\) and the borrow term from the final digit of \(x\), which gives us \(2-1-1=0\).
Generalizing this procedure from decimal numbers to an arbitrary base \(B\) is again straightforward. Given two nonnegative base-\(B\) digits \(x\) and \(y\) with \(x\ge y\), the digits of \(x-y\) are
\(\seteqnumber{0}{11.}{2}\)\begin{equation} r_k = (x_k - y_k + b_{k-1}) \bmod B. \end{equation}
The borrow term \(b_k\) is \(-1\) if there was an underflow while computing the previous digit and 0 otherwise. We have \(b_0=0\) at the beginning since there is no borrow term for the least significant digit. For every other digit, the borrow is defined recursively as
\(\seteqnumber{0}{11.}{3}\)\begin{equation*} b_{k} = \begin{cases} -1 & \text {if $x_k - y_k + b_{k-1} < 0$}\\ 0 & \text {otherwise} \end {cases} \end{equation*}
This can also be written more simply as
\(\seteqnumber{0}{11.}{3}\)\begin{equation*} b_{k} = \bigl \lfloor (x_k - y_k + b_{k-1}) / B\bigr \rfloor \end{equation*}
since the smallest possible value of \(x_k - y_k + b_{k-1}\) is \(-B\) (see Exercise 11.3.) This algorithm for subtracting base-\(B\) integers is summarized in Algorithm 11.2.
Algorithm 11.2
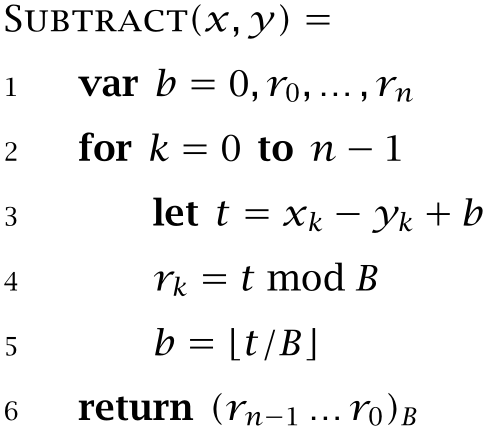
Box 11.2: Complementation In our discussion of the Subtract algorithm we assumed that \(x\ge y\): in this case, the result of the subtraction is non-negative and the final value of the borrow term is 0. But what happens if \(x<y\)? In this case, subtraction produces a somewhat unexpected result. For example, if we try to subtract \(65\) from \(23\), we obtain the following:
| 2 | 3 | \(x\) | ||
| \(-\) | 6 | 5 | \(y\) | |
| \(-\) | 1 | 1 | 0 | borrow term |
| 5 | 8 | \(x-y\) |
The output is \(58\) instead of the correct result \(23-65=-42\), and the only indication that the subtraction underflowed is that the borrow term is 1 at the end of the algorithm.
The incorrect result \(58\) isn’t an arbitrary number but is related to the correct result \(-42\) by the simple equation \(100-42=58\). This is a special case of a more general result: Whenever we subtract a large \(y\) from a smaller number \(x\), Subtract produces a nonzero borrow term and the digits of the number \(B^n-|d|\), where \(B\) is the base of the number system, \(d=x-y\) the correct result, and \(n\) is the number of digits computed. The number \(B^n-x\) is also known as the complement of \(x\) in base-\(B\). We can recover the magnitude of the correct result by complementing a second time, which yields \(B^n-(B^n-|d|)=|d|\).
We already met a special case of complementation in Section 5.2, where we used the two’s-complement \(2^w-x\) to represent negative integers using \(w\) binary digits. We now see why this representation is convenient: If we negate a positive binary number \(x\) by computing \(0-x\) using Subtract, the result is the two’s-complement representation of \(x\). In other words, this is the only representation that is consistent with the standard bitwise subtraction algorithm.
Listing 11.10 shows the implementation of Subtract for big integers. One important difference compared to the implementation of plus() is that \(t=x_k - y_k + b\) can now be negative. As we explained in Section 5.3, the remainder \(t \bmod 2^{31}\) can still be computed using the bitwise AND operator in this case, but to compute the borrow term \(\lfloor t / 2^{31}\rfloor \), we now have to use the arithmetic shift operator ‘>>’. After computing all digits, the method checks whether the final value of the borrow term is nonzero. If it is, the result of the subtraction is not a nonnegative number and cannot be represented as a BigNat; the function throws an exception instead. We will return to the problem of computing with signed integers in Section 11.8.
Listing 11.10ch11 / BigNat
// Subtract two big integers.
public BigNat minus(BigNat y) {
    if (y.size > size)
        throw new ArithmeticException("Underflow");
    int[] result = new int[size];
    int borrow = 0;
    for (int i = 0; i < result.length; i++) {
        int tmp = digit(i) - y.digitOr0(i) + borrow;
        result[i] = tmp & (int) DIGIT_MASK;
        borrow = tmp >> DIGIT_BITS;
    }
    if (borrow != 0)
        throw new ArithmeticException("Underflow");
    return new BigNat(result);
}
Exercises
[11.2]Use induction to show that the carry term \(c\) in algorithm Add is always 0 or 1, regardless of the base \(B\).
[11.3]Use induction to show that the borrow term \(b\) in algorithm Subtract is always 0 or \(-1\), regardless of the base \(B\).
11.4 Multiplication
To find the algorithm for multiplication, we again start with the familiar pen-and-paper method for multiplying decimal numbers. Assume we want to compute \(228\cdot 174\). To do this, we first replace one of the arguments with its decimal expansion, which in this case gives us
\(\seteqnumber{0}{11.}{3}\)\begin{equation*} 228\cdot (100 + 70 + 4) = 228\cdot 100 + 228\cdot 70 + 228\cdot 4. \end{equation*}
Every term on the right-hand side multiplies \(228\) by a number of the form \(10^ky_k\), where \(y_k\) is the \(k\)th digit of \(y=174\). Since multiplication by a power of 10 is equivalent to shifting decimal digits to the left, we can also visualize this process as follows:

The result on the final line is obtained by adding the three intermediate results above it.
Generalizing this idea base-\(B\) integers is straightforward. Again, we first rewrite the product of \(x\) and \(y\) by expanding the multiplier, which reduces the problem of computing \(x\cdot y\) to the simpler problems of multiplying \(x\) by the digits \(y_k\) and then shifting and adding the resulting terms:
\(\seteqnumber{0}{11.}{3}\)\begin{equation} \label {eq:multiply} xy=x\cdot \sum _{k=0}^ny_kB^k = \sum _{k=0}^n x y_kB^k. \end{equation}
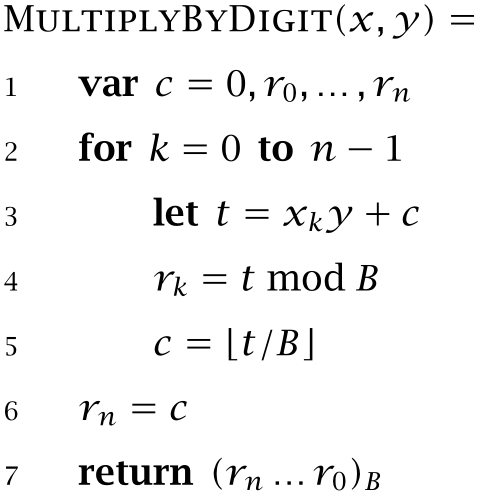
Each product \(x\cdot y_k\) can be computed by multiplying the digits of \(x\) by \(y_k\), starting with the least significant digit and propagating overflows to more significant digits. The resulting algorithm is shown in Algorithm 11.3; except for the computation of \(t\) on line 3, it is identical to the Add algorithm we discussed in the previous section (Algorithm 11.1). With a small modification, MultiplyByDigit can also be used to multiply a number \(x\) by a factor of the form \(y B^{m}\). The only effect of the additional factor \(B^m\) is to shift the digits of the result by \(m\) places, so we simply multiply by \(y\) as before and store each digit in \(r_{k+m}\) instead of \(r_k\).
Algorithm 11.3
To complete the implementation of Eq. (11.4) and obtain the full multiplication algorithm for big integers, we need to wrap MultiplyByDigit in an outer loop that iterates over the digits \(y_k\) of the multiplicator and accumulates all intermediate products \(xy_kB^k\). The resulting algorithm is shown in Algorithm 11.4. It starts by setting all \(n+m\) digits of the result \(r_0,\ldots ,r_{n+m-1}\) to zero and then iterates over the digits of \(y\). The inner loop then multiplies each of these digits by \(x\) and accumulates the terms \(xy_jB^j\) in the variables \(r_0,\ldots ,r_{n+m-1}\). The assignment in line 7 implicitly performs the multiplication by \(B^j\) by writing each digit to \(r_{i+j}\) instead of \(j_i\).
Algorithm 11.4
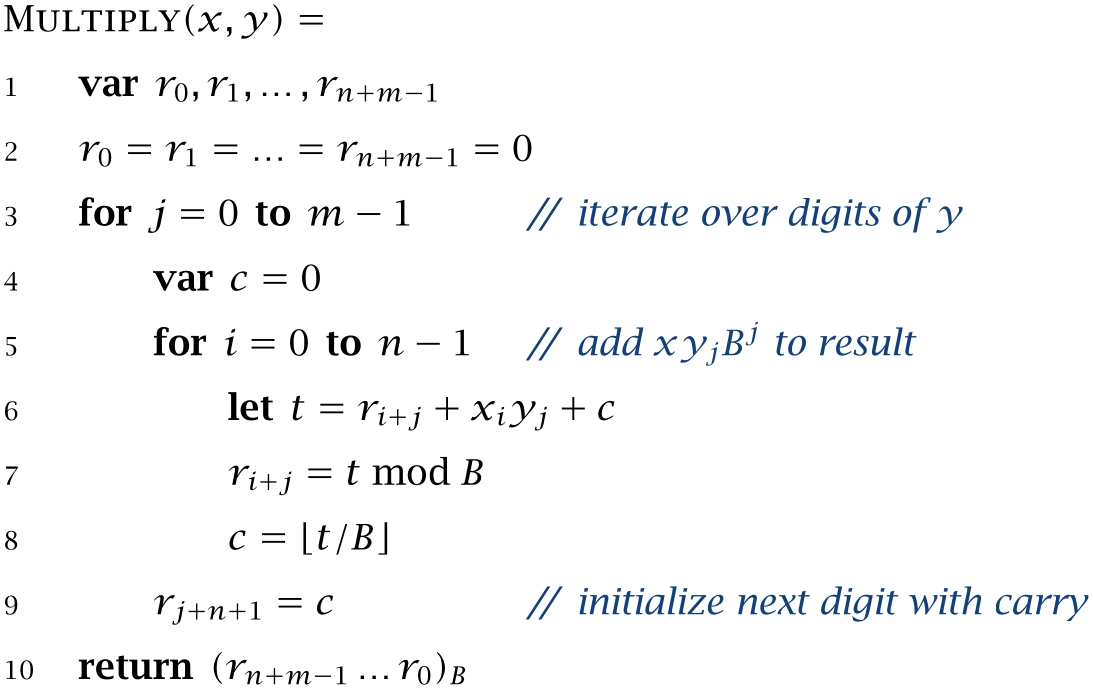
Listing 11.11 shows an implementation of the Multiply algorithm. The two if statements at the start of the function implement two minor optimizations. The first one returns immediately if one of the arguments is zero, whereas the second one exchanges the order of the numbers being multiplied if y has more digits than this. This ensures that the outer of the two loops performs fewer iterations, which reduces the overhead associated with the inner loop. The function then allocates an array result to hold the digits of the result and uses two nested for loops to compute the digits of the result. As in the implementations of plus() and minus(), we replace divisions by BASE and remainder computations with the corresponding bit operations. Notice, however, that the variable tmp must now be declared as long because the expression \(r_{i+j}+x_iy_j+c\) can require up to 62 bits.
Listing 11.11ch11 / BigNat
// Multiply two big integers using the simple algorithm.
public BigNat multiplySimple(BigNat y) {
    if (equals(ZERO) || y.equals(ZERO))
        return ZERO;
    if (size < y.size)
        return y.multiplySimple(this);
    int[] result = new int[size + y.size];
    for (int j = 0; j < y.size; j++) {
        long carry = 0;
        for (int i = 0; i < size; i++) {
            long tmp = (long) result[i + j]
                    + (long) digit(i) * (long) y.digit(j)
                    + carry;
            result[i + j] = (int) (tmp & DIGIT_MASK);
            carry = tmp >>> DIGIT_BITS;
        }
        result[j + size] = (int) carry;
    }
    return new BigNat(result);
}
Compared to addition and subtraction, multiplication is a fairly costly operation. If we assume that the numbers being multiplied have the same length \(n\), the two nested loops of the Multiply algorithm perform a total of \(n^2\) iterations, so the total amount of computational work done is roughly proportional to \(n^2\) — in computer science lingo, the algorithm has a runtime complexity of \(O(n^2)\). In contrast, the Add and Subtract algorithms perform just a single iteration over the digits, and therefore have a complexity of \(O(n)\). (See the following aside for a quick review of growth rates and the big-Oh notation.) It seems that multiplication is intrinsically harder than addition or subtraction: To the best of our knowledge, there is no multiplication algorithm that has a complexity of \(O(n)\). There are, however, several algorithms that improve on the \(O(n^2)\) complexity of Multiply; we will discuss one of them in the following section.
Box 11.3: Growth Rates and the Big-Oh NotationAn algorithm is a procedure that divides a computation into many small, elementary steps. A useful measure for the performance of an algorithm is the total number of steps it requires to compute its result. For simple algorithms, it is sometimes possible to derive an exact formula for the number of steps, but it’s usually sufficient to derive rough estimates of how quickly an algorithm’s running time increases as the size of the input goes up. Such growth rates are often expressed using the so-called big-Oh notation, which tell us how quickly the running time increases as a function of the input size in the worst case. For example, if an algorithm has a complexity of \(O(n^2)\) (“big oh of \(n\) squared”), its running time increases at most quadratically with the size of the input.
Here is an overview of growth rates that commonly occur in the study of algorithms:
-
• \(O(1)\) — The complexity of an algorithm is constant or “in \(O(1)\)” if its running time doesn’t depend on the size of the input.
-
• \(O(\log n)\) — A logarithmic complexity indicates that doubling the size of the input increases the running time only by a constant amount. This complexity is typical for algorithms that repeatedly reduce the size of the input by a constant factor; a classical example is binary search.
-
• \(O(n)\) — If the running time grows at most linearly with the size of the input, it belongs to the class \(O(n)\). Algorithms that perform a constant amount of work for each element of the input belong to this class. Doubling the size of the input also doubles the running time.
-
• \(O(n\log n)\) — This complexity class is also called quasi-linear since the logarithmic part increases so slowly. Many important algorithms such as Quicksort and the Fast Fourier Transform belong to this class.
-
• \(O(n^2)\) — If the running time grows at most quadratically with the size of the input, it belongs to the class \(O(n^2)\). Such algorithms rapidly slow down as the size of the input increases since doubling \(n\) quadruples the running time.
-
• \(O(2^n)\) — If an algorithm has an exponential complexity, the running time increases by a constant factor every time we increase the size of the input by 1. The algorithm we used to construct the Pythagoras tree in Section 3.2 belongs to this class: Adding one layer to the tree doubles the number of rectangles that must be computed. These algorithms are only viable for tiny values of \(n\).
The main benefit of the big-Oh notation is that it allows us to compute with growth rates and easily derive estimates for the worst-case performance of nontrivial algorithms. The mathematical details of this notation and the related big-Theta and big-Omega notations are explained in every text book on algorithms [86, 25].
Exercises
[11.4]Implement MultiplyByDigit (Algorithm 11.3).
⋆ [11.5]Use induction to show that the carry \(c\) in MultiplyByDigit is always less than \(y\).
[11.6]Assume that \(x\) and \(y\) are nonnegative integers with \(n\) and \(m\) digits, respectively. Explain why their product has at most \(n+m\) digits.
[11.7]The Avogadro constant \(N_A\) is defined as the number of atoms or molecules in one mole of a substance. The approximate value of this constant is
\(\seteqnumber{0}{11.}{4}\)\begin{equation} N_A = 6.022\,140\,857\times 10^{23}. \end{equation}
How do you construct \(N_A\) as a BigNat? What numbers are stored in the digits array of the resulting big integer?
11.5 Karatsuba’s Algorithm
As we discussed in the previous section, the Multiply algorithm has a runtime complexity is \(O(n^2)\) since it has to iterate over all pairs of digits of its two operands. Can we do better? There are a few special cases in which the answer is obviously yes. For instance, multiplying by a power of the radix \(B^k\) is as simple as shifting all digits \(k\) places to the left, which only requires a total of \(O(n)\) operations. It’s also clear that no multiplication algorithm can be faster than \(O(n)\) since that’s the time required to store the digits of the result. The question is therefore: Are there any multiplication algorithms with a time complexity between \(O(n)\) and \(O(n^2)\)? The somewhat surprising answer is: Yes, there are several such algorithms, and in this section we will discuss the simplest of them, which is known as Karatsuba multiplication.
Karatsuba’s algorithm is a beautiful example of the divide-and-conquer method. Assume we want to multiply two numbers \(x\) and \(y\), both of which have more than \(m\) digits. We can then split \(x\) and \(y\) into upper and lower parts by writing
\(\seteqnumber{0}{11.}{5}\)\begin{equation} \label {eq:karatsubasplit} x = x_u B^m + x_l,\qquad y = y_u B^m + y_l, \end{equation}
where \(B\) is the base being used. The digits of \(x_u\) and \(x_l\) are the upper and lower digits of \(x\), and likewise for \(y\), \(y_u\), and \(y_l\). For example, if the base-\(B\) representation of \(x\) is
\(\seteqnumber{0}{11.}{6}\)\begin{equation*} x = (x_{n-1}\ldots x_{m} x_{m-1} \ldots x_0)_B, \end{equation*}
we have
\(\seteqnumber{0}{11.}{6}\)\begin{equation*} x_u = (x_{n-1}\ldots x_{m})_B,\qquad x_l = (x_{m-1}\ldots x_{0})_B. \end{equation*}
This is equivalent to splitting a decimal number such as \(x=887\,125\) into two halves by writing \(x=887\cdot 10^3+125\).
With this decomposition, we can now rewrite the product \(x\cdot y\) as follows:
\(\seteqnumber{0}{11.}{6}\)\begin{equation} \label {eq:multdq1} \begin{aligned} xy &= (x_u B^m + x_l)\cdot (y_u B^m + y_l)\\ &= x_uy_uB^{2m} + (x_uy_l+x_ly_u) B^m + x_ly_l\\ &= c_2 B^{2m} + c_1B^m + c_0. \end {aligned} \end{equation}
In the last line we have introduced the following variables:
\(\seteqnumber{0}{11.}{7}\)\begin{equation} \label {eq:multdq2} c_2 = x_uy_u,\qquad c_1 = x_uy_l + x_ly_u\qquad c_0 = x_ly_l. \end{equation}
Since multiplying by a power of \(B\) can be accomplished by shifting the digits of the multiplicand to the left, Eqs. (11.7) and (11.8) reduce the problem of computing \(x\cdot y\) to four simpler multiplications and a handful of simple additions and shifts. Each of the four multiplications in Eq. (11.8) can be decomposed in the same way, and repeating this process recursively ultimately reduces the problem to multiplying individual digits.
As we will discuss in Exercise 11.17, this divide-and-conquer algorithm requires a total of \(O(n^2)\) arithmetic operations to multiply two \(n\)-digit big integers, in other words, it has the same runtime complexity as the Multiply algorithm we discussed in the previous section. A small change to Eq. (11.8) is enough, however, to give the recursive algorithm an unexpected but significant performance boost. The idea is to compute \(c_2\) and \(c_0\) first and then use them to rewrite the expression for \(c_1\) as follows:
\(\seteqnumber{0}{11.}{8}\)\begin{equation} \label {eq:karatsuba2} c_2 = x_uy_u,\qquad c_0 = x_ly_l,\qquad c_1 = (x_u + x_l)(y_u + y_l) - c_0 - c_2. \end{equation}
This is the heart of Karatsuba’s multiplication method. At first glance, the new expression on the right-hand side may not strike you as an improvement: It is more complicated than the old one and increases the number of arithmetic operations from 3 to 5. The main advantage of Eq. (11.9) is that it gets rid of one of the multiplications in Eq. (11.8) — in other words, it trades one multiplications for a few additions and subtractions. This is a net win, not only because adding big integers is cheaper than multiplying them, but also because the multiplications are performed recursively — a single multiplication leads to a cascade of further multiplications — so the savings quickly add up. In fact, the new formula for \(c_1\) reduces the total number of arithmetic operations required to multiply two \(n\)-digit numbers from \(O(n^2)\) to just \(O(n^{1.58})\) steps; again, see Exercise 11.17.
In practice, Karatsuba’s algorithm comes with a certain overhead: We have to split the numbers into smaller pieces, compute the intermediate values \(c_1\), \(c_2\), and \(c_3\), and then combine them to form the final result. As a result, Karatsuba multiplication tends to be slower than the standard multiplication algorithm for small numbers. The exact threshold at which Karatsuba’s method becomes faster depends on implementation details and external factors such as the compiler being used and the underlying hardware. In the description of Karatsuba’s algorithm in Algorithm 11.5 we therefore employ a constant \(N_{\text {min}}\) to determine whether to multiply two numbers using recursive subdivision or the simpler Multiply algorithm. A suitable value for \(N_{\text {min}}\) must be determined by trial and error.
Algorithm 11.5
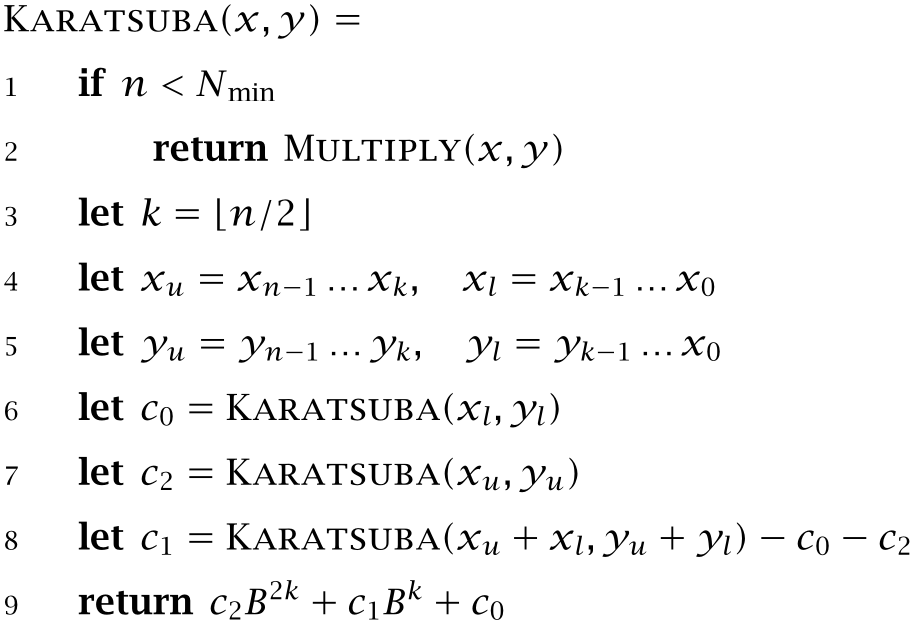
Implementation of Karatsuba’s Algorithm
Let’s turn to the implementation of Karatsuba’s algorithm. Since the first step is to split the digits of the operands \(x\) and \(y\) into lower and upper parts, we first need a way to create a new BigNat from a range of digits of an existing BigNat. One possible implementation is to extract the desired digits using digitOr0() and use them to initialize a new BigNat:
BigNat slice(int first, int n) {
    int[] result = new int[n];
    for (int i = 0; i < n; i++)
        result[i] = digitOr0(first + i);
    return new BigNat(result);
}
We can obtain a more efficient implementation of slice() leaving the array of digits unchanged and modifying the offset and size fields instead. If first is again the offset of the first digit to be extracted and n the number of digits, this process can be visualized as follows:
Extracting the highlighted digits is equivalent to setting the new offset to \(\mathtt {offset}+\mathtt {first}\) and the new size to n. This would give us the following implementation of slice():
The actual implementation of slice() in Listing 11.12 is based on the same idea but handles a few important boundary cases. The function first performs a safety check to ensure that both arguments are nonnegative and then computes the start and end of the desired range of digits. The two calls to min() ensure that the new subarray doesn’t extend beyond the end of the current subarray of digits. The last line of the function creates a new BigNat from the existing array of digits with offset start and length end - start.
Listing 11.12ch11 / BigNat
// Create a new BigNat from a range of existing digits.
private BigNat slice(int first, int n) {
    if (first < 0 || n < 0)
        throw new IllegalArgumentException();
    int start = Math.min(offset + first,
            offset + size);
    int end = Math.min(offset + first + n,
            offset + size);
    return new BigNat(digits, start, end - start);
}
JDK: IllegalArgumentException, Math
•BigNat: BigNat()
Here are a few examples to illustrate how slice() works. We start out by creating BigNat that consists of five digits:
var x = new BigNat(new int[]{ 3, 7, 9, 12, 1 });
We can now use slice() to split this number into an upper and a lower part:
var upper = x.slice(0, 3);   // digits: {3, 7, 9}
var lower = x.slice(3, 2);   // digits: {12, 1}
There are now three instances of BigNat that share the same array of digits but use different values for offset and size.
It is also possible to specify a subarray of digits that extends beyond the most significant digit:
x.slice(3, 3);   // digits: {12, 1, 0} = {12, 1}
x.slice(5, 3);   // digits: {0, 0, 0} = {}
The implementation of slice() assumes that all digits outside the current range are 0.
The times() method in Listing 11.13 demonstrates how to implement Karatsuba’s algorithm for BigNats. Since the standard multiplication algorithm is faster when multiplying small numbers, we call multiplySimple() if either operand has fewer than 100 digits. Otherwise, we split the digits of this and y into upper and lowers parts. The number of digits \(k\) in each part is chosen so that the larger operand is split into two roughly equal parts. This step is cheap since slice() reuses the existing arrays of digits and doesn’t involve any copying. We then apply Eq. (11.9) to compute the constants \(c_0\), \(c_1\), and \(c_2\). The return statement on line 14 computes the final product using the expression \(c_2B^{2k}+c_1B^k+c_0\); the multiplyBasePower() function multiplies a BigNat by a number of the form \(B^n\).
Listing 11.13ch11 / BigNat
// Multiply two big integers.
public BigNat times(BigNat y) {
    if (size < 100 || y.size < 100)
        return multiplySimple(y);
    int k = Math.max(size, y.size) / 2;
    var xl = slice(0, k);
    var xu = slice(k, Math.max(size - k, 0));
    var yl = y.slice(0, k);
    var yu = y.slice(k, Math.max(y.size - k, 0));
    var c0 = xl.times(yl);
    var c2 = xu.times(yu);
    var c1 = xu.plus(xl).times(yu.plus(yl))
            .minus(c0).minus(c2);
    return c2.multiplyBasePower(2 * k)
            .plus(c1.multiplyBasePower(k))
            .plus(c0);
}
The implementation of multiplyBasePower() is shown in Listing 11.14. The function computes \(\mathtt {this}\cdot B^k\) by inserting \(k\) zeros in the least significant digits of this. The method first allocates an array of ints to hold both the shifted digits and the newly added zeros and then copies the existing digits to the subarray starting at inde k. The least significant digits of shifted are automatically initialized to the correct value 0.
Listing 11.14ch11 / BigNat
// Multiply 'this' by the 'k'th power of BASE.
private BigNat multiplyBasePower(int k) {
    int[] shifted = new int[size + k];
    System.arraycopy(digits, offset, shifted, k, size);
    return new BigNat(shifted);
}
Exercises
[11.8]What is the final value of x in the following listing?
BigNat x = new BigNat(new int[]{1, 2, 3})
      .slice(0, 2).slice(1, 2);
11.6 Division and Remainders
We now come to integer division, the last of the four basic arithmetic operations, and the one that is most difficult to implement efficiently. At first, it may not be apparent why division should be more difficult than, say, multiplication. After all, if we are dividing an integer \(u\) by another integer \(v\), all we are asking is “how often does \(v\) fit into \(u\)?” and this question can be easily answered by repeatedly subtracting \(v\) and counting how many iterations it takes until the result is either 0, in which case \(v\) divides \(u\) evenly, or until the result is negative, in which case \(v\) divides \(u\) with a remainder. Unfortunately, this naive “algorithm” is painfully slow — to compute \(1\,000\,000/1\), for instance, it requires a million iterations, even though the result has only seven decimal digits. What we are looking for is an algorithm that finds each digit of the result in a constant amount of time.
Before we go into the details, let’s first clarify the definition of integer division. If \(x\) and \(y\) are two positive integers, their quotient \(q=\idiv {x}{y}\) and remainder \(r=x\bmod y\) are the unique positive integers that satisfy the following two conditions:
\(\seteqnumber{0}{11.}{9}\)\begin{equation} \label {eq:divrem} x = qy + r\qquad \text {and}\qquad r < y. \end{equation}
The first part \(x=qy+r\) tells us that integer division is the inverse of multiplication, whereas the second part \(r<y\) stipulates that the remainder must be as small as possible.
For example, dividing \(x=17\) by \(y=3\) is equivalent to solving the equation \(x=qy+r\) for the quotient \(q\) and the remainder \(r\). There are multiple solutions. One is \(q=1, r=14\) since we have \(17=1\cdot 3+14\), and the others are \((2,11)\), \((3,8)\), \((4,5)\), and \((5,2)\). Only the last solution \(q=5\) and \(r=2\) satisfies the additional constraint \(r<y\), so we have \(\lfloor 17/3\rfloor =5\) and \(17\bmod 3=2\).
Our goal for the remainder of this section is to find an algorithm for integer division that computes both the quotient and the remainder of two arbitrary big integers. We start with the traditional pen-and-paper method for dividing decimal numbers and then make a series of adjustments to handle other radixes and turn the method into a proper algorithm.
The pen-and-paper method for long division computes the digits of the quotient from left to right, starting with the most significant digit. Let’s see this method in action and divide \(x=78\,539\) by \(y=382\). The whole process is usually laid out in a tabular form like this:2
\(\seteqnumber{0}{11.}{10}\)\begin{equation*} \begin{array}{r@{\,}c@{\,}l@{\extracolsep {1cm}}l} &&{\underline {\phantom {00}\mathbf {205}}}\\ 382 &\bigl )& 78539\\ &&\underline {764\phantom {00}} & 382\cdot \mathbf {2}\le 785\\ &&\phantom {0}213 & \text {subtract, bring down next digit}\\ &&\underline {\phantom {000}0\phantom {0}} & 382\cdot \mathbf {0}\le 213\\ &&\phantom {0}2139 & \text {subtract, bring down next digit}\\ &&\underline {\phantom {0}1910} & 382\cdot \mathbf {5}\le 2139\\ &&\phantom {00}229 & \text {remainder} \end {array} \end{equation*}
The three digits \(q_2q_1q_0\) of the result \(205\) are computed sequentially. For the first digit \(q_2\), we determine how often the divisor \(382\) fits into the leading digits \(785\) of the dividend. This can be accomplished using trial and error; here, it’s easy to see that \(2\cdot 382=764\) is barely smaller than \(785\), so the leftmost digit must be \(q_2=2\). Before we compute the next digit, we remove the contribution of \(q_2\) from the dividend by subtracting \(764\) from the leading digits and then append the next digit from \(x\), in this case 3. For the next digit, we have to compute \(213/382\), which immediately gives us \(q_1=0\). We again subtract the contribution of \(q_1\cdot 382=0\) and append the next digit of \(x\).
To find the final digit \(q_0\) we have to divide \(2139\) by \(382\), which requires a bit of trial and error. Since \(3\cdot 7=21\), a reasonable first guess is \(q_0=7\), but a test multiplication shows that this estimate is too large since \(7\cdot 382=2674\). We then try \(6\cdot 382=2292\), which is still too large, and \(5\cdot 382=1910\), which finally gives us a result smaller than \(2139\). The last digit is therefore \(q_0=5\), and performing one more subtraction gives us the remainder \(229\). It is easy to verify that this result is correct: \(205\cdot 382+229=78\,539\).
It is possible to generalize this procedure to numbers in any base \(B\). Assume we want to compute the quotient \(\lfloor x/y\rfloor \) and the remainder \(x\bmod y\) of two arbitrary base-B integers \(x\) and \(y\). If \(x\ge y\), we denote by \(m\) the number of digits in the divisor \(y\) and by \(n\) the number of additional digits in the dividend \(x\); in other words, we have
\[ x=(x_{n+m-1}\ldots x_0)_B,\quad \text {and}\quad y=(y_{m-1}\ldots y_0)_B. \]
With this convention, the quotient has up to \(n+1\) digits and the remainder up to \(m\) digits.
As we will explain in more detail in Box 11.4, the first digit of the quotient \(q_{n}\) can be found by taking the \(m\) most significant digits of \(x\) and dividing them by \(y\):
\[ q_{n} = \bigl \lfloor (x_{n+m-1}\dots x_{n})_B / y\bigr \rfloor . \]
As in the pen-and-paper method, we then subtract \(q_{n}y\) from \((x_{n+m-1}\dots x_{n})_B\) to compute the remainder of the first step
\[ r_{n} = (x_{n+m-1}\dots x_{n})_B - q_{n}y. \]
We can then find the next digit of the quotient by extending \(r_{n}\) with the \(n-1\)th digit from \(x\) and again dividing the result by \(y\). This process is repeated until all \(n+1\) digits \(q_n,\ldots ,q_0\) have been determined.
The resulting algorithm Divide is shown in Algorithm 11.6. Each iteration starts by computing \(t=rB+x_i\), which appends the next digit \(x_i\) of the dividend to the remainder \(r\) of the previous step. Before the loop, \(r\) is initialized to the \(m-1\) most significant digits of \(x\).
Algorithm 11.6
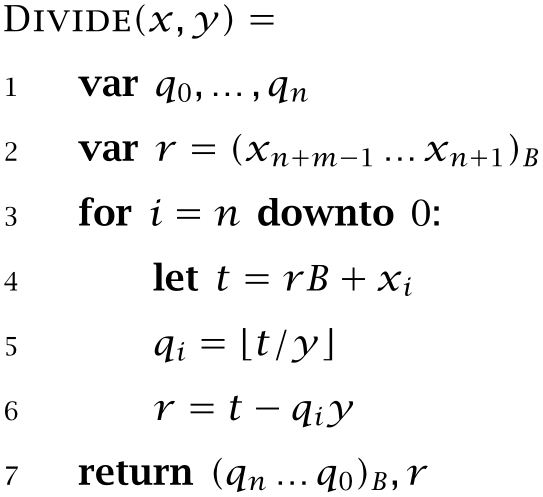
To see that Divide is just a generalized version of the normal pen-and-paper method for long division, let’s use it to divide \(x=78\,539\) by \(y=382\). The divisor \(y\) has three digits, so \(m=3\), and the dividend \(x\) has two additional digits, so \(n=2\). The algorithm now computes the digits \(q_2,q_1,q_0\) in this order. The following table shows the values of all variables used inside the for loop of Divide:
\(\seteqnumber{0}{11.}{10}\)\begin{equation*} \begin{array}{rrrrr} i & t & q_i & r \\ & & & 78 \\ 2 & 785 & 2 & 21 \\ 1 & 213 & 0 & 213\\ 0 & 2139 & 5 & 229\\ \end {array} \end{equation*}
In the first row, the variable \(r\) is initialized to the \(m-1\) most significant digits of \(x\). Each of the following steps then extends the previous value of \(r\) by appending the next digit from \(x\), computes the \(i\)th digit \(q_i=\idiv {t}{y}\), and updates the remainder to \(t-q_iy\).
Notice that algorithm Divide computes each digit of the quotient without resorting to the usual trial-and-error we associate with long division. This assumes, however, that we can evaluate the expression \(\lfloor t/y\rfloor \) directly, which isn’t always the case — after all, \(t\) and \(y\) are still arbitrarily large big integers. Still, computing \(\idiv {t}{y}\) is significantly easier than the original problem \(\idiv {x}{y}\) since we know that the result must be a single digit; we will shortly see why this is important.
Let’s start with a special case in which \(\lfloor t/y\rfloor \) can in fact be evaluated directly. If the divisor \(y\) consists of a single digit, we have \(m=1\) and the division procedure simplifies to the Divide-Digit algorithm shown in Algorithm 11.7. The key property of Divide-Digit is that all quantities used inside the algorithm have only one or two digits: \(y\) and \(r\) are obviously single-digit numbers, and it’s not hard to show that the intermediate value \(t\) has two digits at most (see Exercise 11.10).
Algorithm 11.7
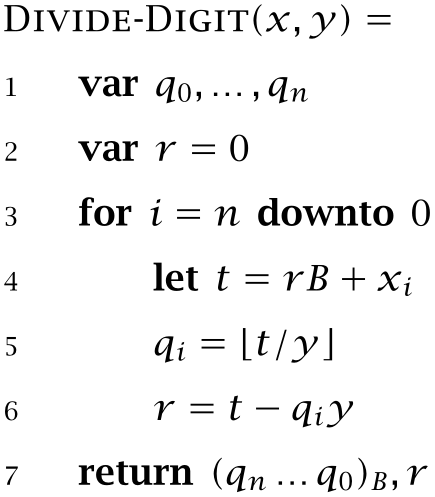
Because Divide-Digit operates on quantities with at most two digits, its implementation for big integers is straightforward. The divideByDigit() method in Listing 11.15 divides a BigNat by a single digit y and returns the quotient and the remainder. The divisor y is of type int and the remaining quantities used by the algorithm are stored in variables of type long. We can therefore use ordinary 64-bit arithmetic compute \(t\), \(q_i\) and \(r\).
Listing 11.15ch11 / BigNat
// Divide 'this' by 'y', return the quotient and remainder.
private BigNat[] divideByDigit(int y) {
    int[] quot = new int[size];
    long r = 0;
    for (int i = size - 1; i >= 0; i--) {
        long t = (r << DIGIT_BITS) + (long) digit(i);
        long qi = t / y;
        quot[i] = (int) qi;
        r = t - y * qi;
    }
    return new BigNat[]{new BigNat(quot), fromUnsignedLong(r)};
}
Box 11.4: Understanding Integer DivisionWhy and how does the division algorithm in Algorithm 11.6 work? It’s easy to understand its mechanics by starting with the inverse operation, the multiplication of two integers:

In the division problem we now take the product \(x=436749\) and the second factor \(y=739\) and try to recover the first factor \(q=\lfloor x/y\rfloor =591\).
Since \(x\) and \(y\) have 6 and 3 digits, respectively, their quotient \(q\) has at most three digits \(q_2q_1q_0\), and the multiplication procedure shown above makes it clear that the most significant digit \(q_2\) only affects the four highest digits of \(x\). We therefore have
\(\seteqnumber{0}{11.}{10}\)\begin{equation} \label {eq:divfirstdigit} 4367 = q_2\cdot 739 + r_2, \end{equation}
where \(r_2\) is the contribution of multiplying 739 by the remaining digits \(q_1\) and \(q_0\). It is possible to show that \(r_2<y\)3, so we can solve Eq. (11.11) for \(q_2\) and \(r_2\) using integer division:
\(\seteqnumber{0}{11.}{11}\)\begin{equation*} q_2 = \lfloor 4367 / 739\rfloor = 5,\qquad r_2 = 4367\bmod 739 = 672. \end{equation*}
We can remove now remove \(q_2\)’s contribution to the product by subtracting \(q_2\cdot 739\) from the leading digits of \(x\), which gives us \(67249\). The problem of finding the remaining digits of \(q\) is now equivalent to inverting the following multiplication:

This problem can be solved in the same way, which gives us the remaining digits \(q_1\) and \(q_0\).
In this example, the final remainder is \(r_0=0\) because 739 divides 436749 evenly. In other division problems, \(r_0\) is equal to the remainder of the original division \(r_0=x \bmod y\) — it’s the remaining term after removing the contributions of each of \(q\)’s digits to \(x\).
2 Slightly different conventions for laying out this table are used in different parts of the world. Here we use the convention common in English-speaking countries.
3 The proof similar to the one in Exercise 11.5.
Finding Digits using Trial and Error
Let’s now turn to the problem of implementing Divide when the divisor \(y\) is not a single digit but an arbitrary big integer. The main problem in this case is computing the \(i\)th digit \(q_i=\lfloor t/y\rfloor \) of the quotient. We know that the correct result \(q_i\) satisfies two conditions:
\[ q_i < B,\qquad \text {and}\qquad q_i y + r = t,\quad \text {with $r < y$}. \]
We can therefore find \(q_i\) by trying all possible digits to find the largest one that satisfies \(q_i y \le t\):

Unfortunately, this approach is prohibitively slow, especially if the radix is large: In our case, it requires up to \(B=2^{31}\) iterations to find just a single digit of the quotient.
We can drastically improve this algorithm by initializing \(q_i\) to a value that is closer to the true result \(\idiv {t}{y}\). The most common strategy for estimating \(q_i\) is to take the two leading digits of \(t\) and divide them by the leading digit of \(y\):
\(\seteqnumber{0}{11.}{11}\)\begin{equation} \label {eq:qhat} \hat q=\left \lfloor \frac {t_{m}\cdot B + t_{m-1}}{y_{m-1}}\right \rfloor . \end{equation}
It can be shown that this estimate always satisfies \(\hat q\ge \lfloor t/y\rfloor \), in other words, it is never smaller than the actual result.4 We can therefore use the same while loop as before to adjust \(q_i\) until it satisfies \(q_i y \le t\):
4 For a proof, see [60, Section 4.3.1].

If \(y_{m-1}\) is small, Eq. (11.12) can overestimate the true result by a lot, so we initialize \(q_i\) to the minimum of \(\hat q\) and \(B-1\).
If we use this technique to compute \(\lfloor t/y\rfloor \) in algorithm Divide, we obtain the updated algorithm for dividing big integers shown in Algorithm 11.8.
Algorithm 11.8
Compute the quotient \(\idiv {x}{y}\) and the remainder \(x\bmod y\) of two integers \(x=(x_{n+m-1}\ldots x_0)_B\) and \(y=(y_{m-1}\ldots y_0)_B\). This is a variation of Algorithm 11.6 that uses only two-digit divisions internally.
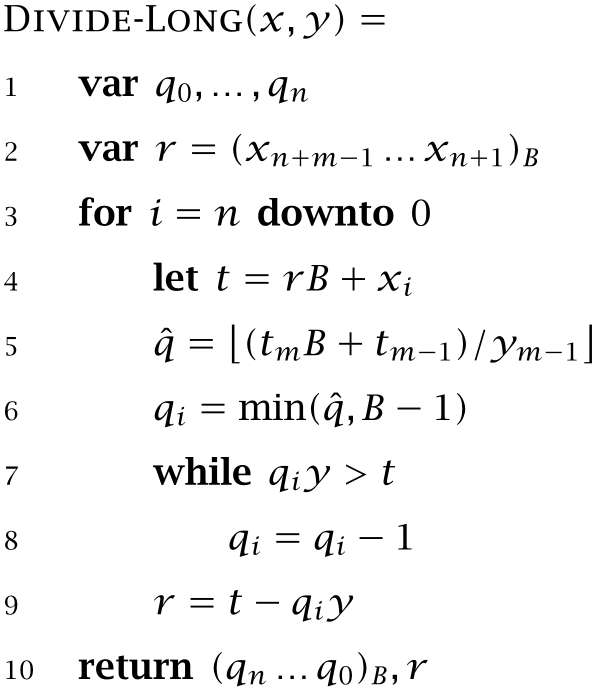
Of course, this algorithm is only better than simply trying all possible digits if \(\hat q\) is close to the true digit \(q_i\). This isn’t always the case, as the following example demonstrates.
Let’s use Divide-Long to compute \(\idiv {1000}{19}\) in the decimal system. We have \(m=2\) and \(n=2\) and the algorithm performs three iterations to compute the digits of the quotient \((q_2q_1q_0)_{10}\). The following table lists the intermediate values computed:
\(\seteqnumber{0}{11.}{12}\)\begin{equation*} \begin{array}{crccc} i & t & \hat q & q_i & r\\ 2 & 010 & \lfloor 01 / 1\rfloor = 1 & 0 & 10\\ 1 & 100 & \min (\lfloor 10 / 1\rfloor , 9) = 9 & 5 & 5\\ 0 & 050 & \lfloor 05 / 1\rfloor = 5 & 2 & 12\\ \end {array} \end{equation*}
The columns for \(\hat q\) and \(q_i\) show the original estimate for \(\idiv {t}{y}\) and the true result; the difference between these two numbers is the number of correction steps performed by the inner while loop. The result is therefore \(\idiv {1000}{19}=052\) with a remainder of \(12\), and the total number of correction steps performed in this case is \(1+4+3=8\).
The algorithm performs much better for other divisors. For example, here are the intermediate values when computing \(\idiv {1000}{52}\):
\(\seteqnumber{0}{11.}{12}\)\begin{equation*} \begin{array}{crccc} i & t & \hat q & q_i & r\\ 2 & 010 & \lfloor 01 / 5\rfloor = 0 & 0 & 10\\ 1 & 100 & \lfloor 10 / 5\rfloor = 2 & 1 & 48\\ 0 & 480 & \lfloor 48 / 5\rfloor = 9 & 9 & 12\\ \end {array} \end{equation*}
In this case, the estimate \(\hat q\) is always close to the true digit \(q_i\) and only a single correction step is necessary in total.
The reason why Divide-Long has to perform more corrections when dividing by 19 than when dividing by 51 is that we use only the leftmost digit \(y_{m-1}\) of the divisor to compute \(\hat q\). If \(y_{m-1}\) is large compared to the remaining digits (as for \(y=52\)), omitting the remaining digits of \(y\) introduces only a small error and \(\hat q\) is close to the true digit. But if \(y_{m-1}\) is relatively small (as for \(y=19\)), we introduce a large error and the estimate \(\hat q\) will be off. In the decimal system, dividing 19, 199, etc. is the worst case scenario that requires up four correction steps per digit. Similarly, the worst case in base-\(B\) is dividing by numbers of the form \((1 (B-1) \ldots (B-1))_B\), in which case up to \(\lfloor B/2\rfloor \) corrections are necessary — that’s still one billion iterations per digit when dividing certain big integers!
Fortunately, there is a simple trick that can be used to ensure that we never need to apply more than a few correction steps. The idea is to multiply both the dividend and divisor of the original division \(x/y\) by a common factor \(\alpha \). This doesn’t change the result of the division since
\(\seteqnumber{0}{11.}{12}\)\begin{equation*} \frac {\alpha x}{\alpha y} = \frac {x}{y}, \end{equation*}
but if we choose \(\alpha \) in such a way that the leading digit of \(\alpha y\) is sufficiently large, we can avoid the worst-case behavior of algorithm Divide-Long. It can be shown that the choice
\(\seteqnumber{0}{11.}{12}\)\begin{equation} \label {eq:divscaling} \alpha = \left \lfloor \frac {B-1}{y_{m-1}+1}\right \rfloor \end{equation}
guarantees that the leading digit of \(\alpha y\) is greater or equal than \(\idiv {B}{2}\) and that in this case no more than two correction steps are required, regardless of the radix \(B\). This is a remarkable improvement that only requires two additional multiplications to compute \(\alpha x\) and \(\alpha y\) and one single-digit division to recover the remainder of \(x\) and \(y\) from the remainder of \(\alpha x\) and \(\alpha y\).
Implementing Long Division
We can finally tie everything together and finish the implementation of integer division. We start with a top-level method for dividing two arbitrary big integers \(x\) and \(y\). We distinguish the following four cases:
-
1. If \(y=0\) we raise an error since division by zero is undefined.
-
2. If \(y\) has a larger magnitude than \(x\), the quotient \(\idiv {x}{y}\) is always 0 and the remainder is \(x\bmod y=x\).
-
3. If \(y\) has just a single digit we use algorithm Divide-Digit.
-
4. If \(y\) has two or more digits we use algorithm Divide-Long.
The divideAndRemainder() function in Listing 11.16 handles division by zero and division by a larger divisor directly and delegates the other two cases to divideByDigit() and divideLong(). All division functions return an array of two BigNats containing the quotient \(\idiv {x}{y}\) and the remainder \(x\bmod y\). For convenience, we also define two methods dividedBy() and remainder() that call divideAndRemainder() and return just the quotient or just the remainder.
Listing 11.16ch11 / BigNat
// Compute the quotient and remainder of this and 'y'.
public BigNat[] divideAndRemainder(BigNat y) {
    if (y.equals(ZERO)) {
        throw new ArithmeticException("Division by zero");
    } else if (this.compareTo(y) < 0) {
        return new BigNat[]{ZERO, this};
    } else if (y.size == 1) {
        return divideByDigit(y.digit(0));
    } else {
        return divideLong(y);
    }
}

public BigNat dividedBy(BigNat y) {
    return divideAndRemainder(y)[0];
}

public BigNat remainder(BigNat y) {
    return divideAndRemainder(y)[1];
}
The implementation of the long division algorithm in Listing 11.17 consists of three methods. The top-level method is divideLong(), which scales the dividend and divisor according to Eq. (11.13) and then calls divideLongInternal() to perform the actual division. Since the scaling factors cancel out, the resulting quotient can be returned as is, but the remainder must be scaled back by dividing it by the scaling factor.
Listing 11.17ch11 / BigNat
private BigNat[] divideLong(BigNat y) {
    int f = (int) ((BASE - 1) / (y.digit(y.size - 1) + 1));
    BigNat[] divRem = this.timesDigit(f)
            .divideLongInternal(y.timesDigit(f));
    return new BigNat[]{divRem[0],
            divRem[1].divideByDigit(f)[0]};
}

private BigNat[] divideLongInternal(BigNat y) {
    int n = size - y.size;
    int m = y.size;
    var r = slice(n + 1, m - 1);
    int[] quot = new int[n + 1];
    for (int i = n; i >= 0; i--) {
        var t = r.appendDigit(digit(i));
        long head = ((long) t.digitOr0(m) << DIGIT_BITS)
                + t.digitOr0(m - 1);
        long qi = Math.min(head / y.digit(m - 1), BASE - 1);
        BigNat yTimesQ = y.timesDigit((int) qi);
        while (t.compareTo(yTimesQ) < 0) {
            qi--;
            yTimesQ = yTimesQ.minus(y);
        }
        quot[i] = (int) qi;
        r = t.minus(yTimesQ);
    }
    return new BigNat[]{new BigNat(quot), r};
}

private BigNat appendDigit(int digit) {
    int[] shifted = new int[size + 1];
    System.arraycopy(digits, offset, shifted, 1, size);
    shifted[0] = digit;
    return new BigNat(shifted);
}
JDK: Math, System
•BigNat: BigNat(), compareTo(),
digit(), digitOr0(), divideByDigit(), minus(),
slice(), timesDigit()
The divideLongInternal() method implements the Divide-Long algorithm in Algorithm 11.8. We first initialize the variables n, m, and r to the same values they have in Divide-Long and then allocate an array quot that holds the digits of the quotient. Each iteration of the for loop then computes one of these digits.
Inside the loop, we use two simple optimizations to speed up our implementation. First, we note that the expression \(t = rB + x_i\) in the original algorithm shifts the digits of \(r\) one place to the left and inserts the next digit \(x_i\) of the dividend as the least significant digit. Instead of performing a multiplication followed by an addition, the appendDigit() method implements this operation by copying the digits to a new array. A second optimization is used in the while loop that adjusts \(q_i\), where we compute the product \(q_i y\) just once before the loop and then adjust it by subtracting \(y\) every time we decrement \(q_i\).
The implementation of long division can be made more efficient by ensuring that no new big integers or arrays of digits are allocated inside the main loop. We can do this by creating two arrays before the loop that hold the digits of t and yTimesQ and then rewriting methods such appendDigit(), compareTo(), and minus() to operate on those arrays.
Exercises
[11.9]The Divide algorithm on page (Page for Algorithm 11.6) requires us to compute \(\lfloor t/y\rfloor \) to find each digit of the quotient. Is it possible to perform this computation by calling Divide recursively?
[11.10]Show that in each iteration of Divide-Digit (Algorithm 11.7) the variable \(t\) satisfies \(t<B^2\) and therefore has at most two digits. Hint: Use the fact that we have \(r=t\bmod y\) and therefore \(r<y\le B-1\).
[11.11]Manually evaluate Divide-Long\((785, 18)\) in the decimal system. Repeat the computation with both arguments scaled by the factor in Eq. (11.13) and compare the total number of correction steps that are necessary.
11.7 Radix Conversion
So far we have only defined a few primitive methods for creating new instances of BigNat: two private constructors that take arrays of base-\(2^{31}\) digits (Listing 11.3) and the fromUnsignedLong() method, which converts a long integer to a BigNat (Listing 11.7). In this section we will discuss how to initialize big integers using a string of decimal digits:
In essence, this fromDecimal() method converts a number specified in base 10 to a BigNat stored in base \(2^{31}\). The opposite conversion is just as important and mostly used for printing numbers or converting them to Strings:
String piString = pi.toString();
// "3141592653589793238462643383279502884197169399"
Here, toString() converts pi from base \(2^{31}\) to a base-10 representation. In general, the process of converting from one base or radix to another is known as radix conversion.
The general problem of radix conversion can be stated as follows. Given an integer \(x=(x_{n-1}x_{n-2}\dots x_1x_0)_b\) in some base \(b\), find the digits of the integer \(y=(y_{m-1}\ldots y_0)_B\) in another base \(B\) that has the same numerical value as \(x\). There are two main methods for determining the digits of \(y\) that differ in whether the old or the new base is used to perform the computations.
The first method is based on the observation that \(y\) must be equal to the base-\(b\) expansion of \(x\):
\(\seteqnumber{0}{11.}{13}\)\begin{equation} \label {eq:decimal} y = x_{n-1}b^{n-1} + x_{n-2}b^{n-2} + \dots + x_{1}b + x_{0}. \end{equation}
If we evaluate the expression on the right-hand side in the new base \(B\), we obtain the digits of \(y\) as a side product. The obvious way to perform this computation is to iterate over the expression from right to left, multiply each \(x_k\) by the corresponding power \(b^k\), and add the resulting terms. If we compute the powers \(b^k\) incrementally, \(1, b, b^2,\dots \), we obtain the From-Radix’ algorithm for radix conversion shown in Algorithm 11.9. The expressions \((x_k)_B\) and \((b)_B\) indicate that the numbers \(x_k\) and \(b\) must be converted to base-\(B\) before they can be used in the surrounding expressions. This conversion is trivial if we are converting to a larger radix, because in this case we have \(x_k<b<B\) and both quantities are single-digit numbers in base-\(B\).
Algorithm 11.9
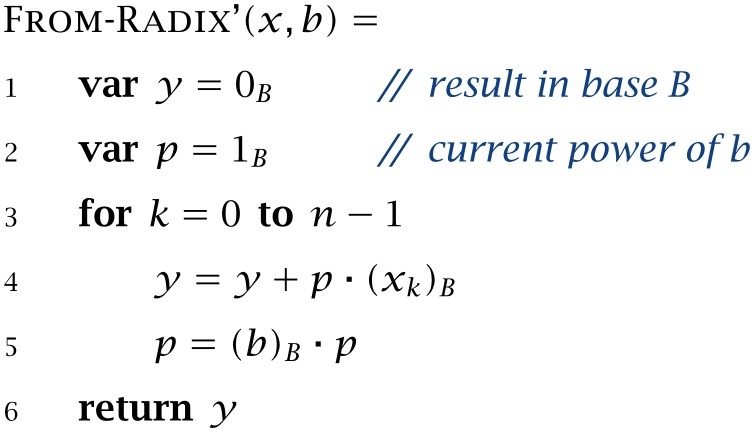
An improved version of From-Radix’ can be obtained by rewriting Eq. (11.14) in the following nested form:
\(\seteqnumber{0}{11.}{14}\)\begin{equation} \label {eq:horner} y = \Bigl (\bigl ((x_{n-1}\cdot b + x_{n-2})\cdot b + x_{n-2}\bigr )\cdot b + \dots \Bigr )\cdot b + x_{0}. \end{equation}
Rewriting polynomial expressions in this way is also known as Horner’s method or Horner’s scheme. Since this expression is evaluated from the inside out, we now have to iterate over the digits of \(x\) in the opposite direction, starting with \(x_{n-1}\) and ending with \(x_0\). The resulting algorithm From-Radix is shown in Algorithm 11.10. The main advantage of Horner’s method is that it requires only half as many multiplications. Since multiplications tend to be significantly more expensive than additions, From-Radix is therefore almost twice as fast than From-Radix’ in practice.
Algorithm 11.10
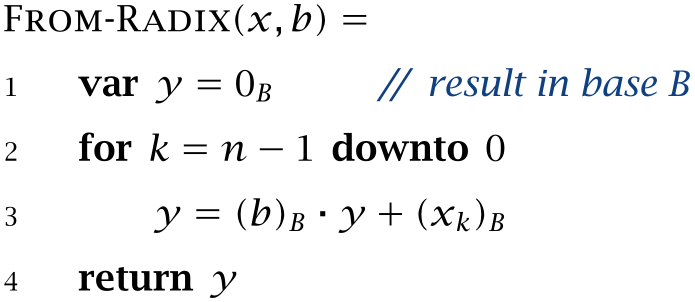
Let’s use From-Radix to convert the binary number \(1101_2\) to decimal. If we follow the steps of the algorithm and write out the intermediate values of all variables, we obtain the following table:
\(\seteqnumber{0}{11.}{15}\)\begin{equation*} \begin{array}{cccc} k & x_k & y & 2y+x_k\\ 3 & 1 & 0 & 1\\ 2 & 1 & 1 & 3\\ 1 & 0 & 3 & 6\\ 0 & 1 & 6 & 13 \end {array} \end{equation*}
The final value is \(13\), which is the decimal representation of \(1101_2\).
Listing 11.18 shows an implementation of From-Radix that takes a String of decimal digits and converts it to a long integer. We start by initializing result and then iterate over the characters of decimal, each of which represents one decimal digit. If the character isn’t one of the decimal digits between '0' and '9' we abort with an exception. Otherwise, we subtract the ASCII code of '0' from that of digit, which gives us an integer with the current digit’s numerical value, and add it to result.
Listing 11.18ch11 / BigNat
// Create 64-bit integer from string of decimal digits.
private static long longFromDecimal(String decimal) {
    if (decimal.isEmpty())
        throw new NumberFormatException("No digits");
    long result = 0;
    for (int i = 0; i < decimal.length(); i++) {
        char digit = decimal.charAt(i);
        if (digit < '0' || digit > '9')
            throw new NumberFormatException(
                    "Invalid decimal digit");
        result = result * 10 + (digit - '0');
    }
    return result;
}
JDK: Character, RuntimeException, String
•BigNat
It’s easy to modify longFromDecimal() to convert a string of decimal digits into a big integer: All we have to do is change the type of result to BigNat and replace the arithmetic operations with calls to times() and plus(), respectively. A significantly faster implementation can be obtained by processing multiple decimal digits at once. To do this, we divide the decimal digits into blocks, convert each block into a long integer using longFromDecimal(), and then accumulate these numbers into a single BigNat. Since the largest positive long integer is larger than \(9\times 10^{18}\), we can handle blocks of up to 18 decimal digits in this way, which reduces the number of BigNat operations that must be performed also by a factor of 18.
For an integer that consists of the first 46 digits of \(\pi \), splitting the number into blocks of 18 digits is equivalent to computing
\(\seteqnumber{0}{11.}{15}\)\begin{equation*} \begin{split} &3141592653589793238462643383279502884197169399\\ &\quad = 3141592653\cdot U^{2} + 589793238462643383\cdot U^{1} + 279502884197169399\\ \end {split} \end{equation*}
with \(U=10^{18}\). Notice that we can again rewrite this expression in a nested form using Horner’s scheme
\(\seteqnumber{0}{11.}{15}\)\begin{equation*} ((3141592653\cdot U + 589793238462643383)\cdot U + 279502884197169399.\\ \end{equation*}
In effect, we treat the input as a number in base \(10^{18}\).
The fromDecimal() method in Listing 11.19 uses this idea to convert a string of decimal digits to a BigNat. The function splits the input decimal into blocks of 18 digits. If the number of digits isn’t divisible by 18, the remaining start digits are used as the first block. Each block is first converted to a long integer using the longFromDecimal() method defined above and then added to the current value result. Compared to a naive implementation of From-Radix, this reduces the number of temporary objects that must be created and the number of BigNat operations by a factor of 18.
Listing 11.19ch11 / BigNat
// Create big integer from a string of decimal digits.
public static BigNat fromDecimal(String decimal) {
    if (decimal.isEmpty())
        throw new NumberFormatException("No digits");
    final int blockSize = 18;
    final BigNat unit = TEN.pow(blockSize);
    final int start = decimal.length() % blockSize;
    BigNat result = start == 0
            ? ZERO
            : fromUnsignedLong(
                    longFromDecimal(decimal.substring(0, start)));
    for (int i = start; i < decimal.length(); i += blockSize) {
        long block =
                longFromDecimal(
                        decimal.substring(i, i + blockSize));
        result = result.times(unit).plus(fromUnsignedLong(block));
    }
    return result;
}
JDK: String
•BigNat: fromUnsignedLong(), longFromDecimal(), plus(), pow(), TEN, times()
One remaining inefficiency of this implementation is that every iteration of the loop creates two temporary BigNat objects that are discarded almost immediately. Since we designed BigNat to be immutable, such temporary objects naturally occur when implementing iterative algorithms; we encountered a similar problem in our discussion of long division in Section 11.6. If required, it is possible to implement From-Radix more efficiently by allocating a sufficiently large array for the digits of the result at the start of the algorithm and then performing all required additions and multiplications in-place.
Let’s turn to the second algorithm for radix conversion. Like From-Radix, this algorithm converts a base-\(b\) number \(x\) to a base-\(B\) number \(y\), but this time all arithmetic operations are performed in the original base \(b\). To find this algorithm, we start with the base-\(B\) expansion of \(y\), which must be equal to the original number \(x\):
\(\seteqnumber{0}{11.}{15}\)\begin{equation} \label {eq:baseB} y_{m-1}B^{m-1}+\ldots +y_1B+y_0 = x. \end{equation}
If we compute the remainder modulo \(B\) on both sides, we see that the rightmost digit of \(y\) must be
\(\seteqnumber{0}{11.}{16}\)\begin{equation*} y_0 = x\bmod B, \end{equation*}
since all other terms on the left-hand side are multiples of \(B\). To find the other digits of \(y\), we divide both sides of Eq. (11.16) by \(B\) to obtain
\(\seteqnumber{0}{11.}{16}\)\begin{equation*} y_{m-1}B^{m-1}+\ldots +y_1 + \underbrace {\lfloor y_0/B\rfloor }_{=0} = \underbrace {\,\lfloor x / B\rfloor \,}_{x'}. \end{equation*}
The next digit is therefore \(y_1=x'\bmod B\), and \(\lfloor x'/B\rfloor \) gives us an equation for the remaining digits of \(y\). We can stop the computation as soon as the division by \(B\) produces zero. The implementation of this algorithm is discussed in Exercise 11.13.
Algorithm 11.11
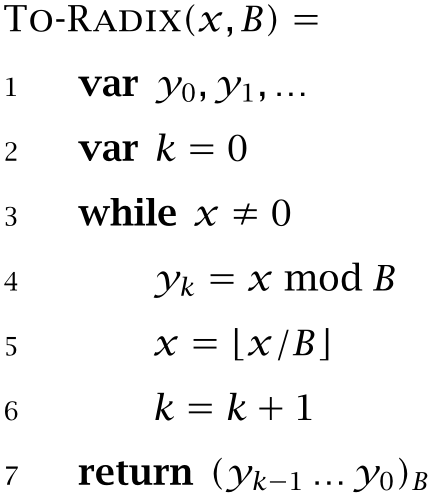
Let’s use this algorithm to find the base-7 representation of 1234? The remainder \(1234\bmod 7=2\) gives us the rightmost digit of the result, and the quotient \(\lfloor 1234/7\rfloor =176\) the number from which we derive the next digit. The remaining digits are obtained by repeatedly computing the remainder modulo 7 and dividing by 7 until the quotient is zero:
\(\seteqnumber{0}{11.}{16}\)\begin{equation*} \begin{array}{cc} 1234 \bmod 7 = 2 & \lfloor 1234 / 7\rfloor = 176\\ 176 \bmod 7 = 1 & \lfloor 176 / 7\rfloor = 25\\ 25 \bmod 7 = 4 & \lfloor 25 / 7\rfloor = 3\\ 3 \bmod 7 = 3 & \lfloor 3 / 7\rfloor = 0 \end {array} \end{equation*}
The results in the left column are the base-7 digits from right to left, so we have \(1234=3412_7\).
Exercises
[11.12]Implement a method with the following signature that converts a string of digits into a long integer:
public static long fromDigits(String digits, int radix);
The two arguments are the digits themselves and their radix, which is assumed to be a number between \(2\) and \(36\). As usual, the characters '0' through '9' represent digits with a numerical value between 0 and 9. In addition, if the radix is greater than 10, digits with a numerical value between 10 and 35 are represented using the letters a through z. The method should throw an exception if an invalid digit is encountered during conversion.
[11.13]Implement a method BigNat.toString() that converts a big integer to a string of decimal digits.
[11.14]A spreadsheet consists of a two-dimensional array of cells, each of which contains a number, a piece of text, or a formula. Each cell has a unique name that encodes its position in the array. The first part of the name is a sequence of uppercase letters that indicates the column of the cell: The letters A to Z refer to columns 1 to 26, AA to AZ refer to columns 27 to 52, BA to BZ to columns 53 to 78, and so on. The second part of the name is a decimal number that indicate the row of the cell. Which column and row does the name XYZ27 refer to? Explain how to convert from cell names to row-column pairs and back. Optional: Implement a class CellName that implements these operations.
[11.15]Explain how to write a computer program that converts from radix 11 to radix 3.
11.8 The Sign-Magnitude Representation
Now that we know how to represent and compute with nonnegative big integers, let’s generalize these ideas to arbitrary signed integers. We first note that every integer \(n\) can be written as the product of its sign and its magnitude[magnitude of an integer]:
\(\seteqnumber{0}{11.}{16}\)\begin{equation} \label {eq:sign-magnitude} n = \sign {n}\cdot |n|. \end{equation}
By convention, \(\sign {n}\) is either \(-1\), \(+1\), or 0, depending on whether \(n\) is negative, positive, or zero. Splitting integers in this way is called sign-magnitude representation. This is the representation we will use for our implementation of signed big integers. The outline of the corresponding class BigInt is shown in Listing 11.20. We store the sign in a regular int and the magnitude in an instance of BigNat. The BigInt class is again immutable.
Listing 11.20ch11 / BigInt
// Represents a signed big integer.
public final class BigInt implements Comparable<BigInt> {
    private final int sign;  // sign: -1, 0, 1
    private final BigNat magnitude;

    // Internal constructor from sign and magnitude.
    BigInt(int sign, BigNat magnitude) {
        this.sign = magnitude.equals(BigNat.ZERO) ? 0 : sign;
        this.magnitude = magnitude;
    }

    // ...
}
JDK: Comparable
•BigNat: equals(), ZERO
The internal constructor BigInt() creates a big integer from a sign and a magnitude. Before initializing the sign and magnitude fields, the constructor performs a simple normalization step to ensure the number zero doesn’t have a nonzero sign. From a mathematical perspective, this normalization isn’t strictly necessary, but it ensures that two BigInts with the same value also have the same internal representation.
Because magnitude cannot be modified, we can safely share its value between different instances of BigInt. This allows us to negate BigInts and compute their absolute value at almost no cost, simply by modifying the sign and reusing the existing magnitude; this gives us the signum(), negate(), and abs() methods shown in Listing 11.21.
Listing 11.21ch11 / BigInt
public int signum() {return sign;}

public BigInt negate() {
    return new BigInt(-sign, magnitude);
}

public BigInt abs() {
    return new BigInt(+1, magnitude);
}
Listing 11.22 shows the implementations of equals() and hashCode(). Two BigInts are equal if their sign and magnitude fields are equal, and their hash codes can be computed by combining the hash codes of sign and magnitude. Notice that this only works if the constructor normalizes the sign as described above: If it were possible to combine a zero magnitude with a nonzero sign, both methods would need to be changed accordingly.
Listing 11.22ch11 / BigInt
public boolean equals(Object o) {
    return (o instanceof BigInt b)
            && sign == b.sign && magnitude.equals(b.magnitude);
}

public int hashCode() {
    return Objects.hash(sign, magnitude);
}
Conversion to and from long integers is slightly more complicated than in the case of BigNat since we have to take the possibility of integer overflow into account. Let’s start with the problem of constructing an instance of BigInt from a value of type long. Listing 11.23 shows a possible implementation of a method valueOf() that performs this conversion. The listing also defines a few commonly used integer constants.
Listing 11.23ch11 / BigInt
public static BigInt valueOf(long v) {
    if (v == Long.MIN_VALUE) {
        return new BigInt(-1, BigNat.fromUnsignedLong(1L << 63));
    } else {
        return new BigInt(Long.signum(v),
                BigNat.fromUnsignedLong(Math.abs(v)));
    }
}

public static final BigInt
        ZERO = valueOf(0),
        ONE = valueOf(1),
        TEN = valueOf(10);
This implementation of valueOf() handles MIN_VALUE as a special case because for this particular value Math.abs(v) overflows and returns a negative result. This is due to a property of two’s-complement representation we mentioned in Section 5.2: the smallest negative number has a greater magnitude than the largest positive number (\(-2^{63}\) vs. \(2^{63}-1\) in the case of 64-bit integers). Therefore, any computation that changes the sign of \(-2^{63}\) — whether by negating it, multiplying it by \(-1\), or computing its absolute value — produces a result that is most likely incorrect. (In this particular example, the code happens to work correctly even if we don’t handle the special case explicitly; we will discuss this in detail below.)
If we want to perform the opposite conversion, from big integers to long integers, we have to take into account that that numbers smaller than Long.MIN_VALUE or larger than Long.MAX_VALUE cannot be stored in the target type. For the similar toUnsignedLong() method in BigNat, we didn’t perform any range checks and simply returned the lowest 64 bits of the big integer. But this time, we would prefer a safer conversion operation that raises an exception if the number cannot be converted to long.
The toLong() method shown in Listing 11.24 performs this kind of safety check before converting a BigInt to long. If the current value is smaller than longMin or larger than longMax it stops and throws an exception. For most other values the function computes the result by multiplying the sign and the lowest 63 bits of the magnitude. To avoid integer overflow, the smallest allowed value Long.MIN_VALUE is again handled explicitly.
Listing 11.24ch11 / BigInt
private static final BigInt
        longMin = valueOf(Long.MIN_VALUE),
        longMax = valueOf(Long.MAX_VALUE);

// Convert to 64-bit integer.
public long toLong() {
    if (compareTo(longMin) < 0 || compareTo(longMax) > 0)
        throw new ArithmeticException("Integer overflow");
    if (compareTo(longMin) == 0)
        return Long.MIN_VALUE;
    return sign * magnitude.toUnsignedLong();
}
Box 11.5: Integer overflow Integer overflow is almost always an error that must prevented before it happens. But in rare circumstances, programs can produce the correct result even if integer overflow occurs in one of the intermediate steps.
The reason is that the result of overflow in two’s-complement arithmetic is always well-defined, even if it’s incorrect or unexpected. When working with signed integers of type int or long, all arithmetic operations are defined to wrap around at either end of the numeric range. For example, incrementing Long.MAX_VALUE by 1 produces a value that doesn’t fit into an long, so the computation wraps around to the other end of the numeric range and produces MIN_VALUE. Similarly, decrementing MIN_VALUE by 1 wraps around in the opposite direction and brings us back to MAX_VALUE. For this reason, the result of the integer expression
(x + 1) - 1
is always x, even if the addition or the subtraction overflows.
Something similar happens when negating the smallest integer MIN_VALUE, which has the value \(-2^{63}\). The correct result \(2^{63}\) is too large for a long integer, so the computation wraps around and produces \(-2^{63}\) again. In two’s-complement representation, we have the paradoxical result that
-MIN_VALUE == MIN_VALUE
In other words, the absolute value of the smallest negative integer MIN_VALUE is MIN_VALUE itself. This is true for any bit width.
We can use these observations to get rid of the special handling of MIN_VALUE in the implementations of BigInt.valueOf() and BigInt.toLong(). The simplified code becomes
public static BigInt valueOf(long v) {
   return new BigInt(Long.signum(v),
                     BigNat.fromBits(Math.abs(v)));
}
and
public long toLong() {
    if (compareTo(longMin) < 0 || compareTo(longMax) > 0)
        throw new ArithmeticException("Integer overflow");
    return sign * magnitude.toUnsignedLong();
}
To see that these implementations are correct, we have to verify that they compute the correct result when converting from or to MIN_VALUE. In the case of valueOf(), this is easy to verify. Since Math.abs() wraps around as described above, the expression
BigNat.fromBits(Math.abs(Long.MIN_VALUE))
is equivalent to
BigNat.fromBits(Long.MIN_VALUE)
The bit pattern of MIN_VALUE is 0x7000000000000000, which is also the bit pattern of the unsigned integer \(2^{63}\), so valueOf() returns \(-2^{63}\) as required.
In the implementation of toLong() we have the reverse situation. For a BigInt with value \(-2^{63}\), the expression
sign * magnitude.toUnsignedLong()
evaluates to
-1 * Long.MIN_VALUE
The multiplication overflows as described above and produces MIN_VALUE, which again happens to be the correct result.
Signed Arithmetic
Last but not least, let’s discuss how basic arithmetic works in the sign-magnitude representation. Suppose we want to add two signed integers \(x\) and \(y\). If the two numbers have the same sign, their sum \(x+y\) has that sign as well and its magnitude is \(|x|+|y|\). If the two numbers have opposite signs, however, the sign of \(x+y\) is the sign of the number with the larger absolute value, and we have to subtract the smaller magnitude from the larger one. We can therefore add two BigInts as demonstrated by the plus() method in Listing 11.25. If this and y have the same sign, we simply add their magnitudes. Otherwise, we determine one with the larger magnitude using compareTo() and subtract the smaller from the larger one. The return statement at the end of the method handles the special case cmp == 0, which occurs when adding a number to its negation. To compute the difference of two BigInts, we simply rewrite \(x-y\) as \(x+(-y)\) and reuse the implementation of plus().
Listing 11.25ch11 / BigInt
// Compute the sum of two big integers.
public BigInt plus(BigInt y) {
    if (sign == y.sign)
        return new BigInt(sign, magnitude.plus(y.magnitude));
    int cmp = magnitude.compareTo(y.magnitude);
    if (cmp > 0)
        return new BigInt(sign, magnitude.minus(y.magnitude));
    if (cmp < 0)
        return new BigInt(y.sign, y.magnitude.minus(magnitude));
    return ZERO;
}

// Compute the difference of two big integers.
public BigInt minus(BigInt y) {
    return plus(y.negate());
}
Multiplying two signed integers \(x\) and \(y\) is easier than adding or subtracting them since both the sign and the magnitude of the product \(x\cdot y\) are obtained by multiplying the signs and magnitudes of the two operands separately:
\(\seteqnumber{0}{11.}{17}\)\begin{align*} \sign (x\cdot y) = \sign x\cdot \sign y,\qquad |x\cdot y| = |x|\cdot |y|. \end{align*} The identities hold for all combinations of signs and magnitudes, in particular for cases where the sign (and the magnitude) are zero.
A similar relationship holds when dividing two signed integers: The sign of the quotient \(\idiv {x}{y}\) is again the product of the individual signs of \(x\) and \(y\), and the magnitude of the quotient is the quotient of the magnitudes:
\(\seteqnumber{0}{11.}{17}\)\begin{align*} \sign \idiv {x}{y} &= \sign x\cdot \sign y,\\ \bigl |\idiv {x}{y}\bigr | &= \bigl \lfloor |x| / |y|\bigr \rfloor . \end{align*} To find the corresponding relationships for the remainders, its easiest to start with the definition
\(\seteqnumber{0}{11.}{17}\)\begin{equation*} x\bmod y = x - \idiv {x}{y}\cdot y \end{equation*}
and infer the influence of the signs of \(x\) and \(y\) from a concrete example. If \(x=\pm 17\) and \(y=\pm 3\), we obtain the following table for the possible quotients and remainders:
\(\seteqnumber{0}{11.}{17}\)\begin{equation*} \begin{array}{r|r|r|r} x & y & \idiv {x}{y} & x\bmod y\\ \hline 17 & 3 & 5 & 2\\ 17 & -3 & -5 & 2\\ -17 & 3 & -5 & -2\\ -17 & -3 & 5 & -2\\ \end {array} \end{equation*}
The sign of the remainder is therefore equal to the sign of \(x\) and its magnitude is just the remainder of \(|x|\) divided by \(|y|\):
\(\seteqnumber{0}{11.}{17}\)\begin{align*} \sign (x\bmod y) &= \sign x,\\ |x\bmod y| &= |x| \bmod |y|. \end{align*} Listing 11.26 shows the code for multiplying and dividing two BigInts.
Listing 11.26ch11 / BigInt
public BigInt times(BigInt y) {
    return new BigInt(sign * y.sign,
            magnitude.times(y.magnitude));
}

public BigInt[] divideAndRemainder(BigInt y) {
    var divRem = magnitude.divideAndRemainder(y.magnitude);
    return new BigInt[]{
            new BigInt(sign * y.sign, divRem[0]),
            new BigInt(sign, divRem[1])};
}

public BigInt dividedBy(BigInt y) {
    return divideAndRemainder(y)[0];
}

public BigInt remainder(BigInt y) {
    return divideAndRemainder(y)[1];
}
Exercises
[11.16]Implement a method compareTo() that performs a three-way comparison of two BigInts.
11.9 Problems
Analysis of Karatsuba Multiplication
⋆ [11.17]The runtime complexity of many divide-and-conquer algorithms can be analyzed using the so-called master theorem. Assume we are given a problem of size \(n\) (in the case of multiplication, \(n\) is the number of digits of the two numbers being multiplied) and let \(T(n)\) denote the time required to solve this problem using a particular algorithm. If the algorithm recursively splits the problem into \(a\) smaller problems of size \(n/b\), we can write \(T(n)\) as
\(\seteqnumber{0}{11.}{17}\)\begin{equation} \label {eq:masterbase} T(n) = aT\left (\frac {n}{b}\right ) + \left (\begin{array}{@{}c@{}} \text {Time required for splitting problem}\\ \text {and combining solutions} \end {array}\right ). \end{equation}
The master theorem now states that \(T(n)\) has the asymptotic complexity
\(\seteqnumber{0}{11.}{18}\)\begin{equation} T(n) = O(n^{\log _b a}), \end{equation}
provided the second term on the right-hand side of Eq. (11.18) is sufficiently small.5
Here is a simple example. In Section 3.1 we discussed a simple recursive algorithm for finding the smallest element in an array of integers. The algorithm splits the array into two parts, recursively finds the minimum of each, and then returns the smaller of the two values. If we split the array into two equal parts, we have \(a=2\) and \(b=2\), so
\[ T(n) = 2\cdot T(n / 2) + C, \]
where \(C\) is a constant that measures the work done before and after the recursive calls, which is independent of \(n\). According to the master theorem, the complexity of the algorithm is therefore
\[ T(n) = O(n^{\log _2 2}) = O(n). \]
-
a) What are the values of \(a\) and \(b\) for the recursive multiplication scheme in Eqs. (11.7) and (11.8)? Assume that master theorem can be applied. What is the resulting asymptotic complexity of \(T(n)\)?
-
b) What are the values of \(a\) and \(b\) for Karatsuba’s algorithm? Again, assume that master theorem can be applied and derive the asymptotic complexity of \(T(n)\).
5 For the technical details and a more general version of the master theorem, see [25, Chapter 4].
Integer Powers
[11.18]Consider the problem of computing \(x^m\) for two integers \(x\) and \(m\). The obvious algorithm computes the product \(x\cdot x\cdot \dots \cdot x\), where \(x\) is repeated \(m\) times, which requires a total number of \(m-1\) multiplications. A much faster algorithm for computing integer powers can be obtained by repeated squaring. It’s easiest to see how it works by considering an example. If we want to compute \(x^{19}\), we start with the binary expansion of the exponent \(19=10011_2=1+2+16\) and then write \(x^{19}\) as a product of three terms of the form \(x^e\), where \(e\) is a power of 2:
\(\seteqnumber{0}{11.}{19}\)\begin{equation*} x^{19}=x^{1+2+16}=xx^2x^{16}. \end{equation*}
Each of the terms \(x^e\) can be obtained by repeatedly squaring the previous term: \(x^2\) is obtained by squaring \(x\) once, and \(x^{16}\) is obtained by squaring \(x^2\) three times:
\(\seteqnumber{0}{11.}{19}\)\begin{equation*} x\xrightarrow {\text {square once}} x^2 \xrightarrow {\text {square 3 times}} x^{16}. \end{equation*}
This method reduces the problem of computing \(x^{19}\) from 18 multiplications to only six multiplications: four multiplications to compute the terms \(x^e\) and two multiplications to accumulate their product.
We can turn this idea into a proper algorithm as follows. Assume we want to compute \(x^m\) for some integer \(x\) and and a positive exponent \(m\). As in the example we just discussed, the first step is to write \(x^m\) as a product of smaller powers of \(x\) using the binary representation of the exponent
\(\seteqnumber{0}{11.}{19}\)\begin{equation*} m = (m_{M-1} \dots m_1m_0)_2 = m_{M-1} 2^{M-1} + \dots + m_1 2^1 + m_0 2^0. \end{equation*}
Using this expansion, we can use the fact that \(x^{a+b}=x^ax^b\) to rewrite \(x^m\) as a product of smaller powers:
\(\seteqnumber{0}{11.}{19}\)\begin{align*} x^m &= x^{m_{M-1} 2^{M-1} + \dots + m_1 2^1 + m_0 2^0}\\ &=x^{m_{M-1} 2^{M-1}} \cdots x^{m_1 2^1} x^{m_0 2^0}; \end{align*} This expression can be simplified further since each bit \(m_k\) is either 0 or 1, which means that each term can be written as
\(\seteqnumber{0}{11.}{19}\)\begin{equation*} x^{m_k 2^k} = \begin{cases} x^{2^k} & \text {if $m_k=1$};\\ 1 & \text {otherwise}. \end {cases} \end{equation*}
Only the terms for which \(m_k=1\) contribute to the final product, so we have our final result:
\(\seteqnumber{0}{11.}{19}\)\begin{equation} x^m = \prod _{0\le k<M, m_k=1} x^{2^k}. \end{equation}
The \(\prod {}\) operator is essentially the mathematical notation for a loop that computes a product of the terms on its right. To translate this expression into an actual loop, we iterate over the nonzero binary digits of the exponent \(m\), and for each such digit \(k\) multiply the result by the term \(x^{2^k}\). The successive terms \(x^{2^k}\) can be easily computed as we go, starting with \(x\) as the first term and computing the following terms \(x^2, x^4, \dots \) by repeated squaring.
-
b) Use this idea to implement an algorithm that computes \(x^k\) for two integers \(x\) and \(k\).
-
c) How many multiplications does this algorithm perform when computing \(x^k\)?
This algorithm for computing \(x^k\) makes only two assumptions: the exponent \(k\) is a nonnegative integer and the base \(x\) is a mathematical object that can be multiplied. We can therefore use the same approach to compute integer powers of other mathematical objects, including real and complex numbers, fractions, and matrices.
-
d) Implement a method BigNat.pow() that computes the integer power of a big integer. Assume that the exponent is of type int.
Decimal Digits
[11.19] A positive integer with decimal digits \(abcde\dots \) is called polydivisible if every number formed by the first \(n\) digits is divisible by \(n\). For example, the number 62 485 is polydivisible because the first digit 6 is divisible by 1, the first two digits 62 are divisible by 2, and the numbers 624, 6248, and 62 485 are divisible by 3, 4, and 5, respectively.
-
a) There are nine polydivisible numbers with a single digit: 1, 2, 3, 4, 5, 6, 7, 8, and 9. How many polydivisible numbers with two digits are there?
-
b) Write a program that computes all polydivisible numbers. How many polydivisible numbers are there? How many digits does the largest polydivisible number have? What is the first polydivisible number that contains all decimal digits exactly once?
[11.20]A rational number is a quotient of the form \(n/m\), where \(n\) and \(m\) are integers. Every rational number has a decimal representation that consists of an integer part and a fractional part. For instance, we have \(7/4=1.75\) with the integer part 1 and the fractional part \(.75\).
-
a) Given two positive integers \(n\) and \(m\), devise an algorithm that computes a certain number of decimal digits of \(n/m\). For example, computing 5 decimal digits of \(7/3\) should produce 2.3333.
-
b) Use this algorithm to compute the first few thousand decimal digits of \(1/998\,001\).
Rational numbers have the following property: their decimal expansion is either finite or eventually produces a sequence of digits that repeats indefinitely; the length of this repeating sequence of digits is called the number’s period. For \(1/4\) the decimal expansion is \(0.25\), which is finite. For \(25/12\), however, the decimal expansion \(2.08\overline {3}\) continues indefinitely; since the repeating sequence consists of a single digit, the number’s period is 1.
-
c) Extend your algorithm to find the shortest sequence of repeating digits in the decimal expansion of \(n/m\). What is the period of \(987\,654\,321/123\,456\,789\)? Hint: Don’t search for repetitions in the sequence of decimal digits. Instead, determine when the algorithm returns to a previous state.
Durations
[11.21]Time durations are traditionally specified in a way that resembles a positional number system. A duration like “three weeks, two days, one hour, five minutes, and ten seconds” can be represented as a sequence of “digits” \(3, 2, 1, 5, 10\) in which each position represents one unit of time. Compared to ordinary number systems, the main difference is that each digit now has its own radix: Seconds and minutes are stored in base-60, hours in base-24, days in base-7, and assuming that weeks are the largest unit we use, we can choose as its radix any sufficiently large integer. Number systems in which each position has its own radix are also known as mixed-radix systems. In this exercise, we will see how arithmetic works in such systems.
-
a) Design a class that stores durations consisting of weeks, days, hours, minutes, and seconds. It should be possible to represent both positive and negative durations. The format should be normalized, so that two durations only have the same representation if they also represent the same time span.
Note: Since the focus of this exercise is on algorithms for mixed-radix systems, durations should be stored as an array of “digits”, not as a single number such as the total number of seconds. For instance, a duration of 70 seconds should be stored as 1 minute and 10 seconds.
-
b) Explain how to compare two durations for equality and how to implement the Comparable interface.
-
c) Define factory methods that construct durations representing a certain number of weeks, days, hours, minutes, or seconds. An example of such a factory method would be a function days() that is declared as follows:
public static Duration days(int n);
In this case, calling days(-8) should return a duration that represents minus 1 week and 1 day.
Also define corresponding methods for querying the number of weeks, days, etc. stored in a duration.
To add and subtract durations, we can use algorithms similar to those for big integers. The main difference is that each unit of time has its own radix, so subtracting 2 seconds from 1 day produces 23 hours, 59 minutes, and 58 seconds.
-
d) Implement methods for adding and subtracting durations.
In our discussion so far we have represented durations using a mixture of units such as “1 hour and 30 minutes”, but it is also possible to express the same durations using single units of time such as “1.5 hours” or “90 minutes” or “5400 seconds”.
-
e) Implement methods such as totalWeeks() or totalDays() that convert a duration to the given unit of time, returning the result as a double.
Computing Pi
[11.22]The problem of computing numerical approximations to \(\pi \) — the ratio of a circle’s circumference to its diameter — has a long and storied history. The first real algorithm for estimating \(\pi \) is due to the Greek mathematician Archimedes of Syracuse.
The idea behind Archimedes’ algorithm is to approximate circles using many-sided polygons. For example, given a circle of radius 1, we can construct two regular \(n\)-sided polygons, one inscribed in the circle and one circumscribed around it, as illustrated in Fig. 11.1. It is clear that the circle’s circumference, which is \(2\pi \), must larger than the perimeter of the inscribed polygon, which we call \(p_n\), but smaller than the perimeter of the circumscribed polygon, which we call \(P_n\):
\(\seteqnumber{0}{11.}{20}\)\begin{equation*} p_n < 2\pi < P_n. \end{equation*}
The more sides the polygons have, the closer they fit the circle, so as we increase \(n\), the values \(p_n\) and \(P_n\) converge toward the true circumference \(2\pi \).
Archimedes’ crucial insight was that it is possible to compute \(p_n\) and \(P_n\) for large values of \(n\) without actually constructing the corresponding polygons. Instead, we can use the following formulas to repeatedly double the number of sides:
\(\seteqnumber{0}{11.}{20}\)\begin{equation} \label {eq:archimedes} p_{2n} = \frac {2p_nP_n}{p_n + P_n},\qquad P_{2n} = \sqrt {p_{2n} P_n}. \end{equation}
This formula is also known as Archimedes’ recurrence formula (see Box 11.6 for a proof). The first identity states that \(p_{2n}\) is the harmonic mean of \(p_n\) and \(P_n\), and the second identity states that \(P_{2n}\) is the geometric mean of \(p_{2n}\) and \(P_n\).
For small \(n\) we can derive the values of \(p_n\) and \(P_n\) geometrically. For \(n=4\) the inscribed square has a side length of \(1/\sqrt {2}\) and the circumscribed square has a side length of 1, so we have \(p_4 = 2\sqrt {2}\) and \(P_4= 4\). Similarly, for \(n=6\) the inscribed and circumscribed hexagons have a side length of \(1/2\) and \(1/\sqrt {3}\), respectively, so the perimeters are \(p_6 = 3\) and \(P_6 =2\sqrt {3}\). Using these starting values we then repeatedly apply Archimedes’ recurrence formula to compute increasingly good estimates of \(\pi \).
-
a) Write a program that computes an approximation to \(\pi \) using Archimedes recurrence formula. Estimate the number of correct decimal digits this algorithm produces per iteration.
Box 11.6: Derivation of Archimedes’ AlgorithmArchimedes’ recurrence formula in Eq. (11.21) is easy to prove using basic trigonometry. The idea is to take a circle of radius 1 and construct inscribed and circumscribed \(n\)-gons as indicated in the following image:
Each segment consists of two right triangles, so the perimeter \(p_n\) of the inscribed polygon and the perimeter \(P_n\) of the circumscribed polygon can be expressed as
\(\seteqnumber{0}{11.}{21}\)\begin{equation*} P_n = 2n\tan \pi /n,\qquad p_n = 2n\sin \pi /n. \end{equation*}
The formulas for \(P_{2n}\) and \(p_{2n}\) now follow from the following trigonometric identities for half angles:
\(\seteqnumber{0}{11.}{21}\)\begin{align*} \tan (\alpha /2)=\frac {\sin \alpha }{1+\cos \alpha } = \frac {1-\cos \alpha }{\sin \alpha },\qquad \sin (\alpha /2)= \sqrt {\frac {1-\cos \alpha }{2}}. \end{align*} By substituting \(\alpha =\pi /n\) we get:
\(\seteqnumber{0}{11.}{21}\)\begin{align*} P_{2n} &= 4n\tan (\alpha /2) = 4n \frac {\sin \alpha }{1 + \cos \alpha } = 4n \frac {\sin \alpha \tan \alpha }{\sin \alpha +\tan \alpha } = \frac {2P_np_n}{P_n + p_n}, \intertext {and} p_{2n} &= 4n\sin (\alpha /2) = \sqrt {8n^2(1-\cos \alpha )} = \sqrt {8n^2\sin \alpha \tan (\alpha /2)} = \sqrt {P_{2n}p_n}. \end{align*}
[11.23]For many centuries, Archimedes’ method remained the best known method for computing \(\pi \), but its slow convergence and the amount of computational work it requires made it hard to use in practice. It wasn’t until the development of calculus in the 17th century — almost two millennia later — that more efficient methods for approximating \(\pi \) finally became available.
The most important formula from this era is Machin’s formula, which relates \(\pi \) to the arctan function:
\(\seteqnumber{0}{11.}{21}\)\begin{equation} \label {eq:machin} \frac {\pi }{4}=4\arctan \frac {1}{5}-\arctan \frac {1}{239}. \end{equation}
The arctan function itself can be approximated very efficiently using its Taylor expansion:
\(\seteqnumber{0}{11.}{22}\)\begin{equation} \label {eq:arctan} \arctan \left (\frac {1}{x}\right ) = \frac {1}{x}-\frac {1}{3x^3} + \frac {1}{5x^5}-\cdots . \end{equation}
For \(x>1\) this series expansion converges very quickly since the denominators grow rapidly.
-
a) Use Machin’s formula to manually compute an approximation to \(\pi \); use the first two terms of the expansion in Eq. (11.23).
It is easy to adapt Machin’s formula to compute digits of \(\pi \) using integer arithmetic only. First, we scale Eq. (11.22) by multiplying both sides by a large integer \(U\):
\(\seteqnumber{0}{11.}{23}\)\begin{equation} \label {eq:machin-scaled} \pi U=16U\arctan \frac {1}{5}-4U\arctan \frac {1}{239}. \end{equation}
If we set \(U=10^k\), the integer part of the right-hand side contains the first \(k\) decimal digits of \(\pi \). To compute this integer part, we first note that \(A\cdot \arctan 1/x\) is
\(\seteqnumber{0}{11.}{24}\)\begin{equation*} A\arctan \left (\frac {1}{x}\right ) = \frac {A}{x}-\frac {A}{3x^3} + \frac {A}{5x^5}-\cdots . \end{equation*}
Now, ignoring the fractional parts of all terms, we replace the divisions on the right-hand side with integer divisions:
\(\seteqnumber{0}{11.}{24}\)\begin{equation} \label {eq:arctan1x} A\cdot \arctan \left (\frac {1}{x}\right ) \approx \left \lfloor \frac {A}{x}\right \rfloor - \left \lfloor \frac {A}{3x^3}\right \rfloor + \left \lfloor \frac {A}{5x^5}\right \rfloor - \cdots \end{equation}
Since the denominators \((2k + 1)x^{2k + 1}\) grow very quickly, almost all of the resulting terms are zero, so we can truncate the series after a finite number of terms.
-
b) Use this approximation to manually compute \(100\pi \).
-
c) Implement Eq. (11.24) and Eq. (11.25) to obtain an algorithm that estimates \(U\pi \) for a given value of \(U\).
In general, we have to be careful when ignoring the fractional parts in a computation like this, but in the case of Machin’s formula, the rounding errors turn out to be fairly minor.
-
d) Use your implementation of Machin’s algorithm to compute \(10^{10000}\pi \). Find a table of \(\pi \) online; how many digits of your result are correct?
11.10 Chapter Notes
The topics we discussed in this chapter belong to the field of computer arithmetic, which studies algorithms and data structures for computing with different kinds of numbers. Computer scientists have come up with a surprising number of data types for representing numbers:
-
• Fixed-width integers are the familiar “computer integers” with a fixed number of bits. We discussed some of their properties in Chapter 5.
-
• Big integers, also known as bignums, can grow to any size, provided there is sufficient memory. We discussed the basic algorithms for working with big integers in this chapter.
-
• Integers modulo \(m\) represent numbers in the range \([0\isep m-1]\); arithmetic operations are defined to wrap around at either end of the range. Such numbers are widely used in number theoretic applications, including cryptography.
-
• Fractions are quotients of form \(n/m\), where \(n\) and \(m\) are two integers. The numerical range of fractions depends on the integer type that is used to store the numerator \(n\) and the denominator \(m\).
Arbitrary-precision fractions, where \(n\) and \(m\) are big integers, correspond to rational numbers in mathematics and are integral to the functioning of computer algebra systems.
-
• Fixed-point numbers are fractions of the form \(n/2^K\), where the numerator \(n\) is a fixed-width integer and the denominator \(2^K\) is a fixed power of 2. For instance, when \(n\) is a 32-bit integer and \(K=16\), this representation lets us store numbers between \(-2^{31}/2^{16}=-32768\) and \((2^{31}-1)/2^{16}\approx 32767.99998\). The main advantages of fixed-point numbers are that only denominator \(n\) needs to be stored and that arithmetic operations are easy to implement.
-
• Floating-point numbers are numbers of the form \(n\cdot 2^e\), where both \(n\) and \(e\) are fixed-width integers. Since the exponent \(e\) is variable, floating point numbers can represent both large and tiny numbers, while still taking up only a fixed number of bits. Floating-point numbers strike a good balance between the flexibility of fractions and the efficiency of fixed-point numbers, but they are much harder to implement than either.
Two good books on computer arithmetic are Modern Computer Arithmetic by Brent and Zimmerman [20] and Volume 2 of The Art of Computer Programming [60]. For floating-point numbers in particular, see the books by Overton [74] and Muller et al. [71].
If you are interested in the implementation of big integers, you may be interested in studying one of the many publicly available implementations. The source code of the BigInteger in Java’s standard library (http://hg.openjdk.java.net/jdk8/jdk8/jdk/file/tip/src/share/classes/java/math/BigInteger.java) is fairly easy to read and implements several advanced arithmetic algorithms. One of the fastest libraries for arbitrary-precision arithmetic is the GNU Multiple Precision Arithmetic Library (GMP) [44].
Over the course of history, mathematicians have come up with many different multiplication algorithms to simplify the nontrivial task of computing the product of two numbers [37]. The ancient Egyptians used a method based on repeated doubling, and a similar method, known as Russian peasant multiplication, is based on repeated halving of one argument and doubling of the other. Our modern table-based algorithm originated in India and evolved into its current form as the Hindu-Arabic numerals (the decimal numbers we now take for granted) slowly took hold in Europe between 1200 and 1800 CE.
For many centuries this method remained the standard algorithm for multiplying numbers. Around 1956, the Soviet mathematician Andrey Kolmogorov conjectured that it is essentially optimal in the sense that no algorithm for multiplying two \(n\)-digit numbers could improve on its runtime complexity of \(O(n^2)\). It took only a few years for this conjecture to be disproved, when Anatoly Karatsuba, one of his Kolmogorov’s own students, came up with the \(O(n^{1.58})\) algorithm discussed in Section 11.5 [57]. This was clearly a major breakthrough, but it also raised two tantalizing questions: Are there even faster multiplication algorithms? Or maybe even a fastest algorithm?
The first improvement on Karatsuba’s method was found independently by Andrei Toom in 1963 [92] and by Stephen Cook in 1966 [24, Chapter 3]. The resulting Toom-Cook algorithm is a relatively simple variation of Karatsuba’s method that improves its runtime complexity to \(O(n^{1.46})\). In 1971, Arnold Schönhage and Volker Strassen discovered an even better algorithm that is based on the fast Fourier transform. Schönhage-Strassen multiplication requires only \(O(n\log n\cdot \log (\log n))\) steps. Since the \(\log (\log n)\) term grows very slowly, Schönhage-Strassen multiplication behaves almost like a \(O(n\log n)\) algorithm and is currently the best practical algorithm for multiplying large integers with thousands of digits.
After Schönhage and Strassen demonstrated that multiplication is almost \(O(n\log n)\), mathematicians started to search for an multiplication method that truly has this complexity. This search took many years and several intermediate steps. In 2007, Martin Fürer first demonstrated how to reduce the \(\log (\log n)\) factor of Schönhage-Strassen multiplication by tweaking the implementation of the fast Fourier transform. Extending this result, in 2019 David Harvey and Joris van der Hoeven finally managed to get rid of the factor altogether to obtain the first multiplication algorithm that requires only \(O(n\log n)\) operations [48, 59].
It is currently conjectured that no multiplication algorithm exists with a better runtime complexity than \(O(n\log n)\). It should be noted, however, that for now the Harvey-van der Hoeven algorithm is mainly of theoretical interest. By their own estimate, the algorithm is faster than Schönhage and Strassen’s only for truly astronomical numbers with more than \(2^{1729^{12}}\) bits!
The number \(\pi \) has a long and storied history that stretches across several millennia and multiple countries. The earliest known approximations to \(\pi \) date back to the ancient Babylonians and Egyptians. A clay tablet found near the city of Susa (dated between 1900 and 1700 BCE) indicates that Babylonian mathematicians approximated \(\pi \) as \(25/8\approx 3.125\), and the Rhind Papyrus, an Egyptian collection of mathematical problems and their solutions (dated to around 1650 BCE) uses the approximation \(256/81\approx 3.16\).
The first real algorithms for computing \(\pi \) were developed by the Greek mathematician Archimedes in the 3rd century BCE and independently by the Chinese mathematician Liu Hui in 263 CE. As discussed in Exercise 11.22, Archimedes’ method is based on the idea of fitting polygons to a circle and makes it possible to compute \(\pi \) to a few decimal digits. The method converges slowly, however, and the required computations become increasingly arduous. It wasn’t until the beginning of the 15th century that the Persian mathematician Jamshīd al-Kāshī finally managed to compute 16 decimal digits of \(\pi \), and in 1600 Ludolph van Ceulen attained a remarkable 35 decimal digits, which corresponds to approximating the circle by \(2.8\times 10^{19}\)-sided polygons! Performing the necessary computations took up a major part of van Ceulen’s life.
The next era in \(\pi \)’s history begins with discovery of calculus in the 17th century and the subsequent development of powerful computational methods such as power series, derivatives, and integrals. Arguably the most important formula for computing \(\pi \) from this era is Machin’s formula, which was discovered by the English astronomer John Machin in 1706:
\(\seteqnumber{0}{11.}{25}\)\begin{equation*} \frac {\pi }{4}=4\arctan \frac {1}{5}-\arctan \frac {1}{239}. \end{equation*}
Machin himself used this formula to compute a record-breaking 100 digits of \(\pi \), and it remained the most efficient method far into the 20th century. In fact, Machin’s formula was used in the very first computer-based computation of \(\pi \): In 1948, George Reitwiesner, John von Neumann, and N.C. Metropolis used it to compute 2037 digits of \(\pi \) on the ENIAC, one of the earliest electronic computers.
With the progress of computer technology after WWII, new \(\pi \) records were now set every few years. As of 2025, 300 trillion decimal digits of \(\pi \) have been computed. All of the recent world records in computing \(\pi \) were achieved using a formula for \(\pi \) that was discovered in 1989 by Gregory and David Chudnovsky:
\(\seteqnumber{0}{11.}{25}\)\begin{equation*} \frac {1}{\pi } = 12\sum _{k=0}^\infty \frac {(-1)^k(6k)!(13591409+545140134k)} {(3k)!(k!)^3640320^{3k+3/2}} \end{equation*}
This Chudnovsky formula converges even more rapidly than Machin’s formula and, despite its daunting appearance, can be implemented very efficiently.
For a more detailed history of \(\pi \) and its computation, see the paper by Bailey et al. [9]. A detailed account of the various formulas and algorithms for computing \(\pi \) that have been devised over the centuries can be found in the book by Arndt and Haenel [6]. As of June 2025, the most advanced program for computing \(\pi \) and many other mathematical constants is y-cruncher [98].