Chapter 5 Bit Basics
The beauty of a living thing
is not the atoms that go into it,
but the way those atoms are put together.
— Carl Sagan, Cosmos
Everything a computer does — every computation it performs, every decision it makes, and every piece of data it stores or transmits — involves reading, writing, or manipulating bits. A single bit is utterly unremarkable: It has two different states one/zero, true/false, or on/off, and the only “computation” we can perform on a single bit is to flip its value from zero to one and vice versa. It’s only when you take groups of bits that things become interesting. With two bits we can already distinguish between four different states, which is enough to define logical operators such as AND, OR, and NOT. With four bits we can store decimal digits and define simple arithmetic operations. Eight bits are enough to store the characters of the Latin alphabet and construct simple microprocessors. And the computer on your desk and the smartphone in your pocket demonstrate what is possible with a few billion bits: You can store basically any kind of information and perform almost any computation imaginable — at least in theory.
In this chapter we will discuss a wide range of programming techniques for computing with bits.
5.1 Storing and Reading Bits
Bits are conventionally stored and processed in groups of 8, 16, 32, or 64 bits. A group of 8 bits is known as a byte, but no standardized terms exist for groups of 16, 32, and 64 bits. Instead, every programming environment and processor manufacturer has its own nomenclature, and a 32-bit quantity may be called a word, doubleword, longword, int, or a long. To avoid confusion, we will call a group of \(w\) bits a \(w\)-bit word or a \(w\)-bit integer. Fortunately, the situation is comparatively easy in Java, where the four integer types byte, short, int, and long are guaranteed to have exactly 8, 16, 32, and 64 bits.
The easiest way to specify bit sequences is to use binary numbers. For example, the following listing initializes the variables a, b, and c with bit sequences of length 8, 16, and 32:
byte a = (byte) 0b01010101;
short b = (short) 0b110011001100110011;
int c = 0b11001100110011001110101011010101
The type casts in the first two lines are necessary because binary constants in Java are always considered 32-bit integers.
As a more interesting example, consider the image shown in Fig. 5.1, which shows a black-and-white image of the ten decimal digits. If we represent every black pixel as a ones and every white pixel as a zeros, we can store such images very compactly in two-dimensional arrays of bits. Such bitmap images were widely used in the earlier days of computing, when display resolutions were low and memory scarce, and they still have many applications ranging from LED displays to retro games.

All digits have a height of 8 pixels, but their widths vary from three pixels for the digit 1 to seven pixels for 4; all other digits are six pixels wide. If we pack the digits right next each other, we can fit the entire image into \(58\times 8\) pixels, so we can store it in eight long integers (Listing 5.1).
Listing 5.1ch5 / BitmapFont
public static long[] digitsImage = {
    0b0111100110111101111110000110111111001110111111011110011110L,
    0b1100111111000110001100001110110000011000000011110011110011L,
    0b1100110110000110011000010110110000110000000011110011110011L,
    0b1100110110000110111100100110111110111110000011011110110011L,
    0b1100110110001100000111000110000011110011000110110011011111L,
    0b1100110110011000000111111111000011110011001100110011000011L,
    0b1100110110110001000110000110100011110011001100110011000110L,
    0b0111100111111110111100000110011110011110001100011110011100L
};
Box 5.1: Hexadecimal Numbers Binary numbers quickly become long and unwieldy. Long bit sequences are therefore often written as hexadecimal (base-\(16\)) numbers to make them more compact. Hexadecimal numbers use 16 digits: the ten decimal digits 0 to 9 and the first six letters of Latin alphabet A to F (in either upper- or lower-case). Translating between binary and hexadecimal numbers is easy because groups of four binary digits correspond to exactly one hexadecimal digit and vice versa:
| Decimal | 0 | 1 | 2 | 3 | 4 | 5 | 6 | 7 |
| Hexadecimal | 0 | 1 | 2 | 3 | 4 | 5 | 6 | 7 |
| Binary | 0000 | 0001 | 0010 | 0011 | 0100 | 0101 | 0110 | 0111 |
| Decimal | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| Hexadecimal | 8 | 9 | A | B | C | D | E | F |
| Binary | 1000 | 1001 | 1010 | 1011 | 1100 | 1101 | 1110 | 1111 |
For example, to obtain the binary representation of 0xC0D3, we look up the bit patterns of C, 0, D, and 3 and combine them to obtain
\(\seteqnumber{0}{5.}{0}\)\begin{equation*} \hexa {C0D3} = 1100\,0000\,1101\,0011_2. \end{equation*}
Conversely, we can convert binary numbers to hexadecimal by splitting bits into groups of four (from the right) and replacing each quadruplet of bits with the corresponding hexadecimal digit. Translating between hexadecimal and binary constants is particularly easy if the bit patterns consist of long runs of ones and zeros, which correspond to runs of F’s and zeros, respectively:
static int allBits = 0xffffffff;
static int highest24Bits = 0xffffff00;
static int lowest8Bits = 0x000000ff;
static int allExceptLowest = 0xfffffffe;
static int allExceptHighest = 0x7fffffff;
What can we do with the bitmap image stored in digitsImage? First of all, we can print the entire image to the screen by iterating over the bits of each row, as shown in Listing 5.2. The outer loop iterates over the rows and the inner loop over the 64 bits of each row, starting with the leftmost bit at position 63 and ending with the rightmost bit at index 0. The expression row & (1L << i) tests whether the \(i\)th bit of row is 1 or 0. It works as follows: We first use a bit shift “<<” to create a bit pattern that consist of a single 1-bit at the \(i\)th position, counted from the right. The AND operator “&” is then used to clear all bits in row except the one we are interested in; the resulting integer is nonzero if this bit is 1 and zero otherwise. Printing the image in digitsImage produces the following output:
 XXXX  XX XXXX XXXXXX    XX XXXXXX  XXX XXXXXX XXXX  XXXX
XX  XXXXXX   XX   XX    XXX XX     XX       XXXX  XXXX  XX
XX  XX XX    XX  XX    X XX XX    XX        XXXX  XXXX  XX
XX  XX XX    XX XXXX  X  XX XXXXX XXXXX     XX XXXX XX  XX
XX  XX XX   XX     XXX   XX     XXXX  XX   XX XX  XX XXXXX
XX  XX XX  XX      XXXXXXXXX    XXXX  XX  XX  XX  XX    XX
XX  XX XX XX   X   XX    XX X   XXXX  XX  XX  XX  XX   XX
 XXXX  XXXXXXXX XXXX     XX  XXXX  XXXX   XX   XXXX  XXX
Listing 5.2ch5 / BitmapFont
public static void printImage(long[] image) {
    for (long row : image) {
        for (int i = 63; i >= 0; i--) {
            long bit = row & (1L << i);
            System.out.print(bit != 0 ? 'X' : ' ');
        }
        System.out.println();
    }
}
JDK: System
More generally, an expression of the form x & m keeps those bits of first argument x that are indicated by the bit pattern of the second argument m. For example, the expression x & 0b10101010 keeps the bits at positions 1, 3, 5, and 7, whereas x & 0b11100 keeps those at positions 2, 3, and 4. A bit pattern that is 1 at certain positions of interest and 0 everywhere else is also called a bit mask.
As a more interesting example of bit masks, let us implement a function drawNumber() that uses the bitmap font defined above to draw an arbitrary decimal number. For example, calling drawNumber("3141592653") should produce a bitmap image that contains the first 10 digits of \(\pi \):
XXXXXX  XX     XX   XX XXXXXX  XXXX   XXXX    XXX  XXXXXX XXXXXX
   XX  XXX    XXX  XXX XX     XX  XX X   XX  XX    XX        XX
  XX    XX   X XX   XX XX     XX  XX     XX XX     XX       XX
 XXXX   XX  X  XX   XX XXXXX  XX  XX     XX XXXXX  XXXXX   XXXX
    XX  XX X   XX   XX     XX  XXXXX    XX  XX  XX     XX     XX
    XX  XX XXXXXXX  XX     XX     XX   XX   XX  XX     XX     XX
X   XX  XX     XX   XX X   XX    XX   XX    XX  XX X   XX X   XX
 XXXX   XX     XX   XX  XXXX   XXX   XXXXXX  XXXX   XXXX   XXXX
The return value of drawNumber() is an array of eight 64-bit integers, one for each row of the resulting image.
The implementation of this function is shown in Listing 5.3. To be able to access the bits that belong to a certain digit, we store its width and position inside digitsImage in two auxiliary arrays width[] and position[]. The width of each digit is measured in pixels (or bits) and its position is the number of pixels to its right. Since the digits are placed right next to each other in digitsImage, each value in position[] is obtained by adding all later entries in width[]; for example, the position of the digit 4 is 30 since the digits 5,6,7,8, and 9 are all six pixels wide. We use these two array to extract bits from digitsImage and combine them into a new image. The outer loop of drawNumber() iterates over the decimal digits to be drawn, and the inner loop copies each digit’s pixels from digitsImage into result.
Listing 5.3ch5 / BitmapFont
static int[] width = {6, 3, 6, 6, 7, 6, 6, 6, 6, 6};
static int[] position = {52, 49, 43, 37, 30, 24, 18, 12, 6, 0};

public static long[] drawNumber(String num) {
    long[] result = new long[digitsImage.length];
    for (int i = 0; i < num.length(); i++) {
        int digit = Character.getNumericValue(num.charAt(i));
        for (int row = 0; row < result.length; row++) {
            long pixels = (digitsImage[row] >>> position[digit])
                    & (1L << width[digit]) - 1;
            result[row] = (result[row] << width[digit] + 1) | pixels;
        }
    }
    return result;
}
JDK: Character, String
•BitmapFont: digitsImage
Inside the loop, we first extract the relevant bits from digitsImage by shifting each row position[digit] places to the right and then applying a bit mask to isolate the lowest remaining width[digit] bits. As we will discuss in the following section, the expression (1 << n) - 1 produces a bit mask that consists of exactly \(n\) ones in the lowest (rightmost) bits. The bits extracted from digitsImage are then drawn to result[] by shifting the current row width[digit] + 1 places to the left and then using a bitwise OR operation to combine the two bit patterns.
Exercises
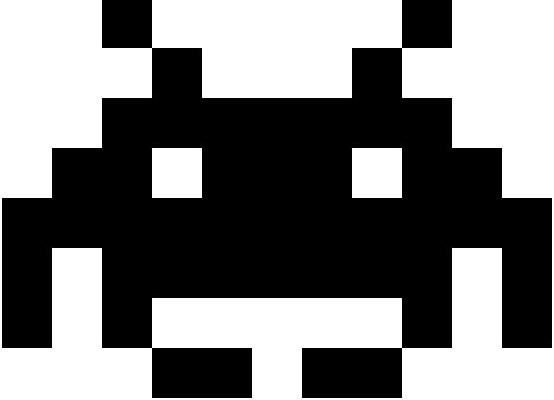
[5.1]A simple text-based file format for exchanging bitmap images is the Portable Bitmap or simply PBM format. Figure 5.2 illustrates how the PBM format encodes a small image of \(11\times 8\) pixels. The first line always contains the marker P1, the second line the width and height of the image, and all the remaining lines encode the image itself. Write a function that outputs the bitmap image stored in an array of long integers as a PBM file.
P1
11 8
0 0 1 0 0 0 0 0 1 0 0
0 0 0 1 0 0 0 1 0 0 0
0 0 1 1 1 1 1 1 1 0 0
0 1 1 0 1 1 1 0 1 1 0
1 1 1 1 1 1 1 1 1 1 1
1 0 1 1 1 1 1 1 1 0 1
1 0 1 0 0 0 0 0 1 0 1
0 0 0 1 1 0 1 1 0 0 0
[5.2]
A bit rotation moves bits to the left or to the right, like a normal bit shift, but bits that are shifted out on one end are re-inserted at the other. We use the functions rotl and rotr to denote rotations to the left and right, respectively. For example, rotating the 32-bit pattern 0b10010111000000000000000000011111 ten places to the left producesrotl(0b10010111000000000000000000011111, 10) => 0b00000000000000000111111001011100
and rotating it ten places to the right produces
rotr(0b10010111000000000000000000011111, 10)
  => 0b00000111111001011100000000000000
Use regular bit shifts and other bit operations to implement two functions rotl() and rotr() that rotate the bits of an int by a certain number of places.
[5.3]Consider the following bit patterns:
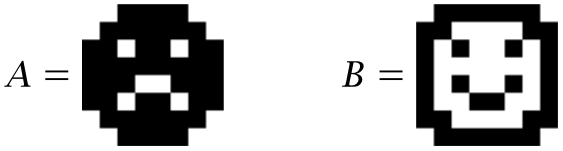
Each image has a size of \(8\times 8\) pixels and can be stored in a single 64-bit integer. Compute \(\NOT A\), \(\NOT B\), \(A\OR B\), \(A\AND B\), and \(A\XOR B\).
[5.4]Write a function that reverses the bytes in an integer. For example, the integer 0xCAFEF00D should be converted to 0x0DF0FECA. Can you perform this byte reversal using only eight bit operations?
5.2 Numbers and Binary Digits
Integer types such as int and long can be interpreted in two ways: as small containers of bits that hold binary data and as ordinary integers that can be added, multiplied, and compared to each other. In this section we take a closer look at the interplay between bit patterns and the numbers they represent.
Two’s-Complement Representation
Computers typically store signed integers in a variation of the binary system known as two’s-complement representation. In this representation, positive integers are stored as ordinary binary numbers, whereas negative numbers are stored in complemented form. Figure 5.3 illustrates how this works in the case of 8-bit integers. The left part of the image shows the bit patterns of nonnegative integers between 0 and 127, which are stored as binary numbers between \(00000000_2\) and \(01111111_2\). The right part shows the bit patterns of negative integers between \(-1\) and \(-128\). Here, each number \(n\) is stored as the binary number \(256+n\), which produces bit patterns between 10000000 and 11111111.
For example, the 8-bit representation of 72 is 01001000 because
\(\seteqnumber{0}{5.}{0}\)\begin{equation*} \begin{aligned} 72 &= 1\cdot 2^6 + 0\cdot 2^5 + 0\cdot 2^4 + 1\cdot 2^3 + 0\cdot 2^2 + 0\cdot 2^1 + 0\cdot 2^0\\ &= 1001000_2. \end {aligned} \end{equation*}
Similarly, the 8-bit representation of \(-93\) is 10100011 because \(256-93=163\) and the binary representation of \(163\) is
\(\seteqnumber{0}{5.}{0}\)\begin{equation*} \begin{aligned} 163 &= 1\cdot 2^7 + 0\cdot 2^6 + 1\cdot 2^5 + 0\cdot 2^4 + 0\cdot 2^3 + 0\cdot 2^2 + 1\cdot 2^1 + 1\cdot 2^0\\ &= 10100011_2.\end {aligned} \end{equation*}
These ideas readily generalize to integers with any number of bits such as 32-bit and 64-bit integers. In the case of \(w\)-bit integers, we have \(2^w\) different bit patterns to work with. The bit patterns are split into two halves, one for nonnegative and one for negative numbers:
| range | bit patterns | |
| nonnegative | 0 to \(2^{w-1}-1\) | \(000\dots 000\) to \(011\dots 111\) |
| negative | \(-2^{w-1}\) to \(-1\) | \(100\dots 000\) to \(111\dots 111\) |
Here are the general rules for converting between numbers and their bit patterns:
-
• Integer \(n\) to bit pattern — If \(n\) is nonnegative, the corresponding bit pattern is the binary representation of \(n\); if \(n\) is negative, it is the binary representation of \(2^w+n\).
-
• Bit pattern to integer — First interpret the bit pattern as an unsigned integer \(x\). If \(x<2^{w-1}\), the bit pattern represents the nonnegative number \(x\); otherwise, it represents the negative number \(x-2^w\).
Notice that the most significant (leftmost) bit is always 0 for nonnegative and 1 for negative numbers. Since the number zero takes up one slot in the positive half of bit patterns, the range of negative integers is one larger than the range of positive integers. For the standard integer types this gives us the ranges shown in Fig. 5.4.
| Type | Bits | Smallest Value | Largest Value |
| byte | 8 | −128 | 127 |
| short | 16 | −32 768 | 32 767 |
| int | 32 | −2 147 483 648 | 2 147 483 647 |
| long | 64 | −9 223 372 036 854 775 808 | 9 223 372 036 854 775 807 |
There is an interesting relationship between each number \(n\) and its negation \(-n\) in two’s-complement representation, which you can find by comparing the two columns in Fig. 5.3: For a positive number \(n\) in the left column, the bit pattern of \(-n\) is obtained by moving up one row and switching to the right column — in other words, by subtracting 1 and then inverting the bit pattern:
\(\seteqnumber{0}{5.}{0}\)\begin{equation} \label {eq:twoscompl-negate} -n = \NOT (n-1). \end{equation}
Similarly, for a negative number \(n\) in the right column, the bit pattern of \(-n\) is obtained by moving down one row and switching to the left column, which also corresponds to subtracting 1 and inverting the bit pattern. Finally, you can convince yourself that the relationship in Eq. (5.1) also holds for \(n=0\).
What does Eq. (5.1) compute if \(n\) is the smallest negative integer \(n=-2^{w-1}\) for a given bit width \(w\)? In this case, both sides of the equation produce a number that cannot be stored as a \(w\)-bit integer — both computations are said to overflow. However, all modern computers define integer overflow in such a way that both sides evaluate to the same bit pattern, so that Eq. (5.1) holds for all \(w\)-bit integers. We will have more to say about integer overflow in Chapter 11.
It’s also instructive to consider how the bit patterns in two’s-complement representation change depending on the bit width \(w\), the number of bits used to store the number. For positive integers, the bit pattern is always the binary representation extended to \(w\) bits, so the number \(87=1010111_2\) has the following 8-, 16-, and 32-bit representations:
| 01010111 | 8 bits |
| 0000000001010111 | 16 bits |
| 00000000000000000000000001010111 | 32 bits |
For negative negative numbers such as \(-17\), we find the bit pattern by adding \(2^w\) and converting the result to binary. For 8-, 16-, and 32-bit integers this gives us \(2^8-17=239\), \(2^{16}-17=65\,519\), and \(2^{32}-17=4\,294\,967\,279\), which results in the following bit patterns:
| 11101111 | 8 bits |
| 1111111111101111 | 16 bits |
| 11111111111111111111111111101111 | 32 bits |
In this case, the bit patterns are extended with ones instead of zeros.
In general, increasing the bit width fills the upper bits of negative integers with ones and those of nonnegative integers with zeros. This is what happens when converting a small integer type such as byte or short to a larger integer type such as int or long. The process is also referred to as sign extension since the new bits are always filled with the most significant bit of the original value, which, as we saw, indicates the sign of the number. To convert a number to a representation with fewer bits, we simply throw away the most significant bits; this is what happens when converting from a large integer type to a smaller one.
Now that we understand the basics of two’s-complement representation, let’s take a closer look at the resulting bit patterns and see if we can find any interesting patterns. We will focus on 8-bit integers between \(-128\) and \(127\) (Fig. 5.5), but everything we will discuss in the following applies to other integer types as well.
Let’s start with a few basics. The bit pattern of 0 consists of zeros only, and the bit pattern of \(-1\) of ones:


Many simple bit patterns that consist of a single run of ones can be constructed by starting with the constant \(-1\) and then shifting the bit pattern to the left or right as required. Here are a few examples:
int allBits = -1;  // 0xffffffff
int highest24Bits = -1 << 8; // 0xffffff00
int lowest8Bits = -1 >>> 24; // 0x000000ff
int allExceptLowest = -1 << 1; // 0xfffffffe
int allExceptHighest = -1 >>> 1; // 0x7fffffff
Numbers of the form \(2^k\), namely \(1, 2, 4, 8, \dots \), have a bit pattern that consists of a single 1 followed by \(k\) zeros.


Any power of \(2\) can therefore be computed by shifting a single bit \(k\) places to the left:
int powerOfTwo = 1 << k;
For all numbers of the form \(2^k-1\), namely \(0, 1, 3, 7, \dots \), the bit pattern consists of exactly \(k\) ones in the least significant bits:


Since numbers of the form \(2^k\) can be written as 1 << k, we can compute a bit pattern whose lowest \(k\) bits are 1 as follows:
int kLowestBitsSet = (1 << k) - 1;
(The parentheses are necessary because the shift operator “<<” has a higher precedence than the minus operator.)
Finally, numbers of the form \(-2^k\), namely \(-1, -2, -4, \dots \), have bit patterns that consist of \(k\) zeros in the rightmost bits and ones everywhere else:


We can use this observation to clear the lowest \(k\) bits of a given value:
int lowestBitsCleared = value & -(1 << k);
Exercises
[5.5]Explain why the \(w\)-bit representation of \(-1\) always consists of \(w\) consecutive 1-bits in two’s-complement representation.
[5.6]Consider a hypothetical computer that stores its numbers as 10-bit integers using two’s-complement representation. What is the range of numbers that can be stored in this format? Fill in the missing entries in the following table:
| number | bit pattern |
| 0 | ? |
| \(-1\) | ? |
| \(489\) | ? |
| \(-384\) | ? |
| ? | 1001011111 |
| ? | 0011100111 |
5.3 Computing with Powers of 2
Powers of 2 and their unique representation in the binary system are the basis of a wide range of clever programming tricks. Let’s start with a fairly obvious one: In every positional number system, we can multiply a number by its radix by appending a single zero to its digits. For example, the product of the decimal number 87 and its radix 10 is \(870\), and the product of the binary number \(1101_2\) and its radix 2 is \(11010_2\). This idea generalizes to multiplication by an integer power of the base, which corresponds to appending multiple zero digits:


What happens if we try the same trick with negative numbers in two’s-complement representation? It turns out that appending \(k\) zeros is again equivalent to multiplying by \(2^k\):


We prove that this works for every negative number at the end of this section.
The equivalent of appending zeros to a number is shifting bits in memory. For example, we can compute \(2n\) using the bit operation \(n\shl 1\), which moves all bits of \(n\) one place to the left and inserts 0 as the least significant bit:
value << 1; // multiply value by 2
Likewise, \(2^kn\) can be computed by shifting by \(k\) places:
value << k; // multiply value by 2**k
If the result of value << k doesn’t fit into the requested number of bits, only the least significant bits of the result are retained. For example, the expression 256 << 31 produces 0 and not the correct result \(2^{39}\), which lies outside the range of 32-bit integers.
Dividing by Powers of 2
If doubling can be implemented by shifting the bit pattern to the left, does halving correspond to shifting to the right? For positive integers this is indeed the case: Shifting one place to the right performs an integer division by 2 and shifting by \(k\) places divides by \(2^k\). For example, shifting the bit pattern of \(109\) one place gives us
\(\seteqnumber{0}{5.}{1}\)\begin{equation*} \lfloor 109 / 2\rfloor = 1101101_2 \shr 1 = 110110_2 = 54, \end{equation*}
and shifting three places
\(\seteqnumber{0}{5.}{1}\)\begin{equation*} \lfloor 109/ 8\rfloor = 1101101_2 \shr 3 = 1101_2 = 13. \end{equation*}
The least significant bits that are shifted out are the remainder of the division. In the last example, we have \(109 = 13\cdot 8 + 5\), and the 3 least significant digits of \(1101101_2\) are indeed \(101_2=5\).
For negative integers, however, a simple right shift doesn’t produce the correct result. For example, if we shift the bit pattern of \(-24\) two places to the right, we obtain the bit pattern of \(58\), a number that is larger in magnitude and has the wrong sign:


Fortunately, it is possible to define a new shift operator “\(\asr \)”, also known as the arithmetic shift operator, that correctly divides both positive and negative numbers. The arithmetic shift \(n \asr k\) performs a normal right shift by \(k\) places and then fills the upper \(k\) bits with ones if \(n\) is negative. In the case of \(-24\asr 2\), this extends the intermediate result \(111010_2\) to the correct 8-bit result:


Notice that the bit pattern \(111010\) of the intermediate result is the 6-bit representation of \(-6\), so you can think of the arithmetic shift as a normal shift followed by a sign extension as discussed in the previous section.
The arithmetic shift operator \(n\asr k\) performs what is called a floor division, which means that the result of dividing by \(2^k\) is rounded to the nearest smaller integer. We can express this mathematically using the floor operator \(\lfloor \cdot {}\rfloor \):
\(\seteqnumber{0}{5.}{1}\)\begin{equation} \label {eq:arithshift} n\asr k = \left \lfloor \frac {n}{2^k} \right \rfloor . \end{equation}
The \(k\) lowest bits of \(n\) that are discarded by the arithmetic right shift have a special significance as well: They form the remainder of the division
\(\seteqnumber{0}{5.}{2}\)\begin{equation} n \AND (2^k -1) = n- \left \lfloor \frac {n}{2^k} \right \rfloor 2^k. \end{equation}
There are many applications in which we want to divide by a power of 2 and round the result up toward the next larger integer. This operation is usually expressed using the ceiling operator \(\lceil \cdot \rceil \):
\(\seteqnumber{0}{5.}{3}\)\begin{equation*} \left \lceil \frac {n}{2^k}\right \rceil . \end{equation*}
(Box 5.2 explains why this operation is useful in practice.) Can we implement this operation using bit shifts as well?
Let’s compare these two rounding modes when dividing by 4. First, here is \(\lfloor n/4\rfloor \) for a few small values of \(n\):

The ceiling operator \(\lceil n/4\rceil \) produces the same result if \(n\) is evenly divisible by 4, but it rounds up to the next integer otherwise:

Comparing these two diagrams makes it clear that the two functions are closely related: In both cases, exactly four integers in the top row are mapped to a particular quotient in the bottom row. The only difference is that the upper row is offset by \(-3\) in the case of the ceiling operator (for example, the numbers that are mapped to 0 are \(0,1,2,3\) for the floor operator and \(-3,-2,-1,0\) for the ceiling). This means that we can compute \(\lceil n/4\rceil \) adding 3 to the input and then performing a floor division, and for an arbitrary power of 2, we have
\(\seteqnumber{0}{5.}{3}\)\begin{equation} \left \lceil \frac {x}{2^k}\right \rceil = \left \lfloor \frac {x+2^k-1}{2^k}\right \rfloor = (x + 2^k - 1) \asr k. \end{equation}
For fixed values of the exponent \(k\) this trick is often used as an inline expression; for instance, (x + 7) >> 3 performs a division by 8 rounded up to the nearest integer.
Trailing Zeros
The bit patterns of even numbers end with a 0 and those of odd numbers with a 1. Here are a few examples of even numbers


and of odd numbers


We can therefore check whether a number is even or odd by inspecting its least significant bit:
static boolean isEven(int value) {
    return (value & 1) == 0;
}

static boolean isOdd(int value) {
    return (value & 1) != 0;
}
In both functions the rightmost bit of value is isolated using the expression value & 1.
This is a special case of a more general property of numbers in two’s-complement representation: The number of trailing zeros indicates how often a number is evenly divisible by 2: If a number has a single trailing zero, it is divisible by 2; if it has two trailing zeros, it is divisible by 4; if it has three trailing zeros, it is divisible by 8; and so on. This works for positive as well as negative integers:


We can use this observation to round down any integer \(x\) to the nearest multiple of \(2^k\) by clearing its \(k\) least significant bits. Mathematically, this can be expressed as follows: To round to the next smaller multiple of \(2^k\), we first divide by \(2^k\), then round to the nearest smaller integer using the floor operator, and finally scale the result back to the original range:
\(\seteqnumber{0}{5.}{4}\)\begin{equation} \label {eq:floorpow2} \left \lfloor \frac {x}{2^k}\right \rfloor 2^k = x \AND (2^k-1). \end{equation}
We can define a similar operation for rounding to the next greater multiple of \(2^k\) by replacing the floor operator with the ceiling operator \(\lceil \cdot \rceil \):
\(\seteqnumber{0}{5.}{5}\)\begin{equation} \label {eq:ceilpow2} \left \lceil \frac {x}{2^k}\right \rceil 2^k = \left \lfloor \frac {x + 2^k-1}{2^k}\right \rfloor 2^k = (x+2^k - 1) \AND (2^k-1). \end{equation}
For fixed values of the exponent \(k\) this trick is often used as an inline expression; for instance, (x + 0b11) & ~0b11 rounds up to the nearest multiple of 4.
Box 5.2: Partitioning Memory Programs that work with large amounts of data — including operating systems, databases, or image processing applications — often have to partition this data into smaller fixed-size chunks that can be stored or processed independently. Bit tricks can simplify and speed up this kind of partitioning.
Let’s say the original data consists of \(N=22\) items, which we split into chunks of size \(M=8\). This results in two full chunks of size 8 and one final chunk that contains the remaining 6 items:

With this kind of partioning, we replace the single index \(i\) in the original data with a double index \((c,p)\), where \(c\) is the index of the chunk and \(p\) the position inside the chunk. It’s easy to convert between these two addressing modes:
\(\seteqnumber{0}{5.}{6}\)\begin{gather*} i=cM+p,\qquad c=\lfloor i/M\rfloor ,\qquad p=i\bmod m \end{gather*} The total number of chunks is \(\lceil N/M\rceil \) and the final chunk contains \(N-\lfloor N/M\rfloor M\) items.
If we make the size of each such chunk a power of 2, say \(M=2^e\), all the divisions and multiplications can be replaced with bit operations:
| Quantity | Arbitrary \(M\) | \(M=2^e\) |
| chunk that contains index \(i\) | \(\lfloor i/M\rfloor \) | \(i \asr e\) |
| position of index \(i\) inside chunk | \(i\bmod M\) | \(i \AND (M-1)\) |
| first index in chunk \(c\) | \(mc\) | \(c \shl e\) |
| number of complete chunks | \(\lfloor N/M\rfloor \) | \(N\asr e\) |
| number of chunks | \(\lceil N/M\rceil \) | \((N + M-1)\asr e\) |
| items in final incomplete chunk | \(N\bmod M\) | \(N \AND (M-1)\) |
Because these operations are so efficient, computer memory is almost always measured in powers of 2: A byte consists of 8 bits, a long integer of 8 bytes, and operating systems divide the computer’s RAM into pages of \(4096=2^{12}\) bytes, and so on. Even the size of physical RAM modules is generally measured in powers of 2, from \(2^{20}\) bytes (MiB) to \(2^{30}\) bytes (GiB).
Leading Zeros and Logarithms
In this section we will discuss one last quantity that is derived from the bit pattern of a number \(n\): the number of leading zeros \(\text {nlz}(n)\). This quantity is only defined for numbers that are stored in a fixed number of bits and counts the number of zeros to the left of the most significant bit. Here are a few examples:


For negative numbers the number of leading zeros is 0 since the leftmost bit is always set in two’s-complement representation. But for nonnegative integers there is an interesting pattern: For \(w\)-bit integers, the function starts at \(\text {nlz}(0)=w\) and then decreases by 1 every time we reach a new power of 2. The following table shows the value for the 8-bit integers in Fig. 5.5:
| \(n\) | 1 | \(2\isep 3\) | \(4\isep 7\) | \(8\isep 15\) | \(16\isep 31\) | \(32\isep 63\) | \(64\isep 127\) |
| \(\text {nlz}(n)\) | 7 | 6 | 5 | 4 | 3 | 2 | 1 |
The reason is obvious: Every time we reach a new power of 2, an additional binary digit is needed, which in turn reduces the number of leading zeros by 1.
It’s therefore no surprise that the number of leading zeros of a number \(n\) is closely related to its binary logarithm \(\log _2 n\), in particular the integer part \(\lfloor \log _2 n\rfloor \). Figure 5.6 compares these three functions for 8-bit integers. It’s easy to see that the number of leading zeros is inversely related to \(\lfloor \log _2 n\rfloor \):
\(\seteqnumber{0}{5.}{6}\)\begin{equation*} \lfloor \log _2 n\rfloor = 7-\text {nlz}(n). \end{equation*}
A similar relationship holds for \(w\)-bit integers:
\(\seteqnumber{0}{5.}{6}\)\begin{equation} \label {eq:floorlog2} \lfloor \log _2 n\rfloor = w-1-\text {nlz}(n). \end{equation}
This is a simple way to compute the integer part of the base-2 logarithm without having to resort to floating point arithmetic.
We can find a similar trick for computing the binary logarithm rounded to the next larger integer by comparing \(\lfloor \log _2 n \rfloor \) and \(\lceil \log _2 n \rceil \) for a few small values of \(n\):
\(\seteqnumber{0}{5.}{7}\)\begin{equation*} \begin{array}{c|c|c|c|c|c|c|c|c|c|c|c|c|c|c|c} n & 1 & 2 & 3 & 4 & 5 & 6 & 7 & 8 & 9 & 10 & 11 & 12 & 13 & 14 & 15\\ \hline \lfloor \log _2n\rfloor & 0 & 1 & 1 & 2 & 2 & 2 & 2 & 3 & 3 & 3 & 3 & 3 & 3 & 3 & 3\\ \lceil \log _2n\rceil & 0 & 1 & 2 & 2 & 3 & 3 & 3 & 3 & 4 & 4 & 4 & 4 & 4 & 4 & 4\\ \end {array} \end{equation*}
If you shift the upper row one place to the right and increment every value by 1 you obtain the lower row, so we have
\(\seteqnumber{0}{5.}{7}\)\begin{equation*} \lceil \log _2 n\rceil = \begin{cases} \lfloor \log _2(n-1)\rfloor +1 & n>1\\ 0 & n=1 \end {cases} \end{equation*}
Together with Eq. (5.7) this gives us an expression in terms of the number of leading zeros:
\(\seteqnumber{0}{5.}{7}\)\begin{equation} \label {eq:ceillog2} \lceil \log _2 n\rceil = w-\text {nlz}(n-1). \end{equation}
The special case for \(n=1\) disappears because \(\text {nlz}(0)=w\). The ceiling of \(\log _2\) is particularly useful in practice because it lets us round a positive integer \(n\) to the nearest power of 2 that is at least as large as \(n\), which can be expressed as \(2^{\lceil \log _2 n\rceil }. \) We will discuss an application in Section 10.2.
Functions that implement these two variations of the binary logarithm are shown in Listing 5.4. The first function floorBinaryLog() computes \(\lfloor \log _2 n\rfloor \) using Eq. (5.7) and the second function ceilBinaryLog() computes \(\lceil \log _2 n\rceil \) using Eq. (5.8).
Listing 5.4ch5 / IntMath
// Compute the binary logarithm, rounded down.
public static int floorBinaryLog(int value) {
    if (value < 1)
        throw new ArithmeticException("log of number <= 0");
    return 31 - Integer.numberOfLeadingZeros(value);
}

// Compute the binary logarithm, rounded up.
public static int ceilBinaryLog(int value) {
    if (value < 1)
        throw new ArithmeticException("log of number <= 0");
    return 32 - Integer.numberOfLeadingZeros(value - 1);
}
JDK: ArithmeticException, Integer
Exercises
[5.7]What does the expression (x << 1) | 1 compute, assuming that x is of type int?
[5.8]What is the result of -1 >>> k and -1 >> k?
[5.9]On binary computers, integer multiplications by positive constants can sometimes be implemented more efficiently by replacing them with a combination of bit shifts and additions. The expression \(15x\), for instance, can implemented as
(x << 3) + (x << 2) + (x << 1) + x
Explain why this trick works and how to compute \(298x\) using bit shifts and additions. Bonus question: Can you compute \(15x\) using fewer shifts or additions?
5.4 Bit Sets
So far we have treated the bits in an integer as abstract “bit patterns,” but there is an alternative interpretation that is just as useful. If we identify each bit with its position in the pattern, a group of bits can also be regarded as a set of integers. For instance, a group of four bits can represent all possible sets of the four integers \(0, 1, 2, 3\):
\(\seteqnumber{0}{5.}{8}\)\begin{equation*} \begin{array}{@{}llll@{}} {0000} = \emptyset & {0001} = \{0\} & {0010} = \{1\} & {0011} = \{0,1\}\\ {0100} = \{2\} & {0101} = \{0, 2\}& {0110} = \{1, 2\}& {0111} = \{0, 1, 2\}\\ {1000} = \{3\}& {1001} = \{0, 3\}& {1010} = \{1, 3\}& {1011} = \{0,1, 3\}\\ {1100} = \{2, 3\}& {1101} = \{0, 2, 3\}& {1110} = \{1, 2, 3\}& {1111} = \{0, 1, 2, 3\}\\ \end {array} \end{equation*}
The \(k\)th bit is set to 1 if the number \(k\) is contained in the set. The same idea works for any number of bits: There is a one-to-one correspondence between \(n\)-bit patterns and sets of integers in the range \(0\isep n-1\). Bit patterns that are used in this way are also called bit sets. When working with sets of small integers, bit sets consume far less memory than other set data structures, and they are also significantly faster. As we will see, most set operations can be expressed using simple bit operations.
Constructing Bit Sets
Let’s start with a few ways of constructing bit sets. The empty set \(\emptyset \) is trivial to construct since it is always represented by the number 0, and for singleton sets that contain a single integer \(\{k\}\), the corresponding bit set consists of a single bit at position \(k\), which we can construct by shifting 1 the required number of places to the left:
\(\seteqnumber{0}{5.}{8}\)\begin{align*} \emptyset \quad &\longleftrightarrow \quad 0\\ \{k\}\quad &\longleftrightarrow \quad 1 \shl k \end{align*} The bitwise OR of two or more such singleton sets produces a bit set that contains multiple integers. For instance, the bit set that contains two integers \(k\) and \(l\) has 1-bits at those same positions:
\(\seteqnumber{0}{5.}{8}\)\begin{align*} \{k,l\}\quad &\longleftrightarrow \quad (1\shl k) \OR (1\shl l). \end{align*} Similar relationships hold for more than two elements.
The functions bit() and bits() in Listing 5.5 implement these two operations and return long integers with bits at the specified positions. Notice that the bits() function has normal set semantics in the sense that its arguments can be in any order and can contain duplicates. For instance, just as \(\{3, 3, 1\} \) and \(\{1, 3\}\) denote the same set of integers, the two calls bits(3, 3, 1) and bits(1, 3) produce the same bit set.
Listing 5.5ch5 / Bits
// Return a long integer that has the k-th bit set.
public static long bit(int k) {return 1L << k;}

// Return a long integer that has the specified bits set.
public static long bits(int... positions) {
    long bits = 0;
    for (int n : positions)
        bits |= 1L << n;
    return bits;
}
A different approach is useful for constructing bit sets that consist of a sequence of consecutive integers. As we discussed in Section 5.2, the bit pattern of \(2^n-1\) consists of \(n\) ones in the least significant bits and zeros elsewhere, whereas the bit pattern of \(-2^n\) consists of \(n\) zeros in the least significant and ones elsewhere. We therefore have the following correspondence between sets and bit sets:
\(\seteqnumber{0}{5.}{8}\)\begin{align*} \{0,1,\ldots ,n-1\}\quad &\longleftrightarrow \quad 2^{n}-1\\ \{n,n+1,\ldots ,63\}\quad &\longleftrightarrow \quad -2^{n} \end{align*} Likewise, the set \(\{k, k+1, \ldots , k+n-1\}\) can be obtained by first computing \(2^n-1\) and then shifting the result \(k\) places to the left. The two functions in Listing 5.6 use these identities to create bit sets for ranges of integers. The first range() function with two arguments creates a bit set that includes every integer from first up to but not including stop. For instance, range(0,0) returns the empty set and range(5, 8) the set \(\{5, 6, 7\}\). The range() function with one argument creates a bit set that includes the numbers between first and 63.
Listing 5.6ch5 / Bits
// The bit set containing the numbers first to stop (exclusive).
public static long range(int first, int stop) {
    int n = stop - first;
    long nBits = n == 64 ? -1L : (1L << n) - 1;
    return nBits << first;
}

// The bit set containing the numbers from first to 63.
public static long range(int first) {
    return -(1L << first);
}
A technical detail is worth noting about the implementation of range(). In line 4, where we compute a bit pattern that contains n 1-bits, we handle the case for n == 64 specially. This is necessary because in Java all shift operators don’t behave as expected when shifting a long by 64 or more places or a int by 32 or more places. The details are explained in the following note.
The precise rules Java uses to evaluate bit shifts are somewhat arcane because they are modeled after the behavior of bit shift instructions on microprocessors in the 1990s. The general rule is that bit shifts of the form x << k, x >> k, and x >>> k use only the lowest six bits of k when x is a 64-bit integer and only the lowest five bits when x is a 32-bit integer. For this reason, the expression 1L << 64 is equivalent to 1L << 0 because the lowest six bits of 64 are zero; similarly, 1L << 65 is equivalent to 1L << 1. An unfortunate consequence of this rule is that 1L << 64 produces a different result than (1L << 63) << 1. Because this is rarely the expected outcome, it is usually best to shift by at most 63 or 31 places and handle other cases explicitly.
Set Operations
In the implementations of bits() in Listing 5.5, we used the bitwise OR operator to combine multiple individual bits. It’s not hard to see that the OR operator computes the union of two bit sets in general. For example, the union of the two sets \(A=\{1, 4, 7\}\) and \(B=\{0, 5, 7\}\) is \(\{0, 1, 4, 5, 7\}\), and for the corresponding bit sets we have
\(\seteqnumber{0}{5.}{8}\)\begin{equation*} \begin{array}{rr} S & \bits {10010010}\\ T & \bits {10100001}\\ \midrule S \OR T & \bits {10110011} \end {array} \end{equation*}
Similarly, the bitwise AND operator computes the intersection of two sets, that is, the set of all elements that are contained in both sets. The intersection of \(\{1, 4, 7\}\) and \(\{0, 5, 7\}\) is \(\{7\}\), and for the corresponding bits sets we have
\(\seteqnumber{0}{5.}{8}\)\begin{equation*} \begin{array}{rr} S & \bits {10010010}\\ T & \bits {10100001}\\ \midrule S\AND T & \bits {10000000} \end {array} \end{equation*}
Just like the intersection of two sets determines which elements they have in common, the intersection of two bit sets determines which 1-bits they have in common. We therefore have the following correspondences:
\(\seteqnumber{0}{5.}{8}\)\begin{equation*} \boxed { \begin{aligned} S\cup T\quad &\longleftrightarrow \quad S \OR T\\ S\cap T\quad &\longleftrightarrow \quad S \AND T \end {aligned} } \end{equation*}
Finally, the set difference \(S-T\) is defined as the set of elements that are contained in \(S\) but not in \(T\). For example, if \(S=\{1, 4, 7\}\) and \(T=\{0, 5, 7\}\), the set difference is \(S-T=\{1, 4\}\). Conceptually, there are two ways to compute the set difference: You either remove the elements of \(S\) that are also contained in \(T\), or you retain the elements of \(S\) that are not contained in \(T\). This second definition can be expressed as the intersection of \(S\) with the complement of \(T\), that is, the set \(\overline {T}\) that contains all elements that are not in \(T\):
\(\seteqnumber{0}{5.}{8}\)\begin{equation} \label {eq:setdiff} S-T = S \cap \overline {T}. \end{equation}
If \(S=\{1, 4, 7\}\) and \(T=\{0, 5, 7\}\), as in the example above, the set difference can be computes as
\(\seteqnumber{0}{5.}{9}\)\begin{equation*} S-T = \{1, 4, 7\} \cap \{1, 2, 3, 4, 6, 8, \ldots \} = \{1, 4\}. \end{equation*}
The set \(\{1, 2, 3, 4, 6, 8, \ldots \}\) contains all integers except 0, 5, and 7.
The main advantage of expressing set differences in this way is that Eq. (5.9) can be translated directly into bit operations. The complement of a bit set is obtained by inverting all bits using the NOT operator, so the set difference \(S-T\) can be written as S & ~T:
\(\seteqnumber{0}{5.}{9}\)\begin{equation*} \boxed { S-T\quad \longleftrightarrow \quad S\AND \NOT T } \end{equation*}
For instance, if \(S=\bits {10010010}\) and \(T=\bits {10100001}\), the complement of \(T\) is \(\NOT T=\bits {01011110}\) and the set difference \(S\AND \NOT T\) becomes
\(\seteqnumber{0}{5.}{9}\)\begin{equation*} \begin{array}{rr} S & \bits {10010010}\\ \NOT T & \bits {01011110}\\ \midrule S \AND \NOT T & \bits {00010010} \end {array} \end{equation*}
The resulting bit pattern 00010010 can again be interpreted as the set \(\{1, 4\}\).
We can use set intersections to implement several important membership tests for bit sets. For example, two sets share no elements if their intersection is empty, and at least one element if it is nonempty. Similarly, if \(S\) is any set and \(x\) is a single element, the intersection \(S\cap \{x\}\) is empty only if \(S\) doesn’t contain \(x\) :
\(\seteqnumber{0}{5.}{9}\)\begin{equation*} x\in S\quad \iff \quad S\cap \{x\}\ne \emptyset \end{equation*}
Evaluating the right-hand side is trivial for bit sets: A bit set s contains a number k if s & (1 << k) is nonzero.
\(\seteqnumber{0}{5.}{9}\)\begin{equation*} \boxed { x\in S\quad \longleftrightarrow \quad S\AND (1\shl x) \not =0 } \end{equation*}
The functions containsNone(), containsSome(), and contains() in Listing 5.7 implement these three operations for bit sets.
Listing 5.7ch5 / Bits
// Return true if the bit sets 's' and 't' are disjoint.
public static boolean containsNone(long s, long t) {
    return (s & t) == 0;
}

// Return true if the bit sets 's' and 't' have common elements.
public static boolean containsSome(long s, long t) {
    return (s & t) != 0;
}

// Return true if the bit set 'set' contains the number 'k'.
public static boolean contains(long set, int k) {
    return (set & (1L << k)) != 0;
}

// Return true if the bitset 't' is a subset of 's'.
public static boolean containsAll(long s, long t) {
    return (s & t) == t;
}
Finally, \(T\) is a subset of \(S\) if the intersection of \(S\) and \(T\) is equal to \(T\):
\(\seteqnumber{0}{5.}{9}\)\begin{equation*} T\subseteq S\quad \text {if and only if}\quad S\cap T=T. \end{equation*}
For bit sets, the right-hand side again translates to a simple expression involving bit operations:
\[ \boxed { T\subseteq S \quad \longleftrightarrow \quad S \AND T = T } \]
The function containsAll() in Listing 5.7 can be used to test whether one bit set is a subset of another. A summary of set operations and their implementation using bits is provided in Fig. 5.7.
|
Operation |
Sets | Bit sets |
|
Empty set |
\(\emptyset \) | 0 |
|
Singleton set |
\(\{x\}\) | 1 << x, bit(x) |
|
Sets of integers |
\(\{x_0, x_1,\ldots \}\) | (1 << x0) | (1 << x1) | ... |
| bits(x0, x1, ...) | ||
| \(\{a, a+1, \ldots , b-1\}\) | range(a, b) | |
| \(\{a, a+1, \ldots , 63\}\) | range(a) | |
|
Complement |
\(\overline S\) | ~s |
|
Intersection |
\(S\cap T\) | s & t |
|
Union |
\(S\cup T\) | s | t |
|
Difference |
\(S-T\) | s & ~t |
|
Containment |
\(x\in S\) | s & (1 << x) != 0 |
|
Equality |
\(S=T\) | s == t |
|
Subset |
\(T\subseteq S\) | (s & t) == t |
Exercises
[5.10]Given two bit sets s and t, what is the meaning of the expression (s | t) == t?
[5.11]If \(S\) and \(T\) are bit sets, what is the interpretation of \(S\XOR T\), where “\(\XOR \)” is the XOR operator?
5.5 Iterating over Bits
In the previous sections we discussed how to construct bit sets and how to use bit operations to modify all set elements at once. But there are also situations where we need to process the elements of a set individually, for example if we want to print them or convert them to another data structure. The easiest way to iterate over the elements of a bit set is to iterate over all 64 bits and perform a certain action for those bits that are set to 1. For example, we can convert a bit set bits to a list of integers as follows:
var elements = new ArrayList<Integer>();
long mask = 1L;
for (int i = 0; i < 64; i++) {
    if ((bits & mask) != 0)
        elements.add(i);
    mask <<= 1;
}
Obviously, this solution requires exactly 64 iterations, regardless of the contents of bits.
We can speed up this loop by skipping over long runs of 0-bits. To do this, we use the numberOfTrailingZeros() function defined in class Long, which computes the number of trailing zeros in an integer. The updated loop looks as follows:
while (bits != 0) {
    int i = Long.numberOfTrailingZeros(bits);
    elements.add(i);
    bits &= ~(1L << i);
}
In each iteration, the loop finds the rightmost 1-bit in bits, adds its position to elements, and then removes this bit from bits. The loop terminates as soon as all 1-bits have been processed, and the number of iterations is now equal to the total number of 1-bits. We can make one final improvement to this loop by employing a clever programming trick: If \(n\) is any number in two’s-complement representation, the expression \(n \AND (n-1)\) clears the least significant 1-bit of \(n\), so we can replace the final line inside the loop to obtain the following implementation:
while (bits != 0) {
    int i = Long.numberOfTrailingZeros(bits);
    elements.add(i);
    bits &= bits - 1;  // clear least significant bit
}
To understand how this trick works, we first note that subtracting 1 from any binary number toggles the least significant 1-bit and all the bits below it. To see this, consider the following two examples:
\(\seteqnumber{0}{5.}{9}\)\begin{equation*} \begin{array}{lcc} & n=47 & n=44 \\ n & 101111_2 & 101100_2 \\ n-1 & 101110_2 & 101011_2 \\ n \AND (n-1) & 101110_2 & 101000_2 \end {array} \end{equation*}
If \(n\) is an odd number, subtracting 1 simply changes the least significant bit from 1 to 0; in this example, \(47=101111_2\) becomes \(46=101110_2\). If \(n\) is an even number, subtracting 1 changes all trailing 0-bits to 1 and the least significant 1-bit to 0; here, \(44=101100_2\) becomes \(43=101011_2\). In both cases the remaining bits are left unchanged, so the final step \(n\AND (n-1)\) has the net effect of clearing the least significant 1-bit of \(n\). We will see in Exercise 5.12 that the trick also works if \(n\) is negative or 0; the expression \(n\AND (n-1)\) therefore clears the lowest 1-bit for all integers in two’s-complement representation.
Bit Iterators
To make it even easier to iterate over the bits of an integer, we can encapsulate the explicit loops discussed in the previous section in a data type known as an iterator. Iterators retrieve successive elements of a data structure by providing two operations: one to retrieve the current element and one to advance to the next element. Iterators are commonly used with complex data structures such as linked lists or hash tables, but they are easily adapted to our use case.
In Java, The standard interface for iterators Iterator is parametrized by the type of the elements stored in the data structure.1 When iterating over bit patterns, the elements produced by the iterator are the positions of the 1-bits, so the element type is Integer. A complete implementation of this interface for iterating over the bits of a long is shown in Listing 5.8.
Listing 5.8ch5 / BitIterator
// Iterate over the 1-bits of an integer.
public class BitIterator implements Iterator<Integer> {
    private long remaining;

    public BitIterator(long bits) {remaining = bits;}

    @Override
    public boolean hasNext() {
        return remaining != 0;
    }

    @Override
    public Integer next() {
        int i = Long.numberOfTrailingZeros(remaining);
        remaining &= remaining - 1;  // clear least significant bit
        return i;
    }
}
The hasNext() and next() methods are specified by the Iterator interface. The hasNext() method determines whether there are any additional elements in the sequence; this is the case if there are additional nonzero bits in remaining. The next() method fetches the next element in the sequence and advances the iterator. In our case, we find the next element in remaining by counting the trailing zeros and then advance the iterator by clearing the least significant bit.
We can now write a loop that iterates over bits by creating an instance of BitIterator and then calling next() repeatedly until hasNext() returns false:
var iter = new BitIterator(bits);
while (iter.hasNext()) {
    elements.add(iter.next());
}
As a final improvement, we can define a helper method iterate() that lets us use regular for loops to iterate over bits:
for (int i : Bits.iterate(bits)) {
    elements.add(i);
}
The iterate() method takes an integer and returns an object of type Iterable, which is then used by Java to create code equivalent to the while loop shown above. The implementation of iterate() is shown in Listing 5.9; the following remark explain the technical details of this short method.
Listing 5.9ch5 / Bits
// Create an iterator for the 1-bits of value.
public static Iterable<Integer> iterate(long value) {
    return () -> new BitIterator(value);
}

// Return the positions of all 1-bits.
public static List<Integer> toList(long bits) {
    var result = new ArrayList<Integer>();
    for (int i : iterate(bits))
        result.add(i);
    return result;
}
JDK: ArrayList, Integer, Iterable, List
•BitIterator: BitIterator()
The expression
() -> new BitIterator(value);
in the implementation of Bits.iterate() is a so-called lambda expression or anonymous function, which creates a simple function whose body consists of the code after the arrow “->”. In Java, lambda expressions can be used to implement interfaces that consist of single method. This particular lambda expression is equivalent to creating a new instance of Iterable as follows:
new Iterable<Integer>() {
    public Iterator<Integer> iterator() {
        return new BitIterator(value);
    }
};
A review of lambda expressions and related programming techniques can be found in Appendix B.6.
1 See Appendix B.5 for an introduction to iterators in Java.
Exercises
[5.12]We discussed in the text why the expression \(n \AND (n - 1)\) clears the least significant bit of every positive integer \(n\). Explain why this trick also works for negative integers and the number zero in two’s-complement representation.
[5.13]Use the expression \(n \AND (n-1)\) to count the number of 1-bits in an integer. (This quantity is called the population count or the bit count; see also Exercise 5.17).
[5.14]Explain how to use bit operations to test whether a number \(n\) is a power of 2, that is, whether it is of the form \(2^{k}\) for some value \(k\).
5.6 Problems
Cellular Automata
[5.15]A cellular automaton is a simple “machine” that can change its internal state in response to the states of nearby automata. We already met such automata in Exercise 2.6: in the Game of Life, cells live and die on a two-dimensional grid depending on the number of neighbors in their immediate vicinity.
In this exercise we are concerned with elementary cellular automata, which are the simplest such automata: They have two internal states, on or off, and are influenced by their direct neighbors to the left and right. The behavior of such an automaton can be specified graphically as follows:
The three squares in the top row show the current state of a cell and its two neighbors. Since each cell can be either on or off, there are \(2^3=8\) different configurations of these three cells. The single square in the bottom row indicates the new state of the cell in the center. For example, the first column tells us that a cell turns off if it is surrounded by two active cells. This transition table is also called the automaton’s rule.
We can visualize the behavior of different rules by starting with a row of cells in which only the one in the center is on:

We assume that cells wrap around, which means that the leftmost and rightmost cells are considered neighbors; this convention is also known as periodic boundary conditions. We can now determine the new state of each cell using the rule shown above. Since most cells and their neighbors are off, the last column of the rule tells us that they remain off; The exception are the three cells in the center, which turn on. After the first step the cells are in the following state:

In the next generation, the three cells in the center have more than one active cell in their neighborhood so they turn off, but the two cells on the boundary turn on:

If you continue in this way and stack all the generations on top of each other, you obtain the image shown in Fig. 5.8. It’s our old friend the Sierpiński triangle, this time produced using a cellular automaton.
-
a) Consider the rule shown in the following picture:
Start again with a single active cell and manually construct the next five generations. What pattern do you observe?
In our discussion so far, we have described cellular automata in a tabular form, by listing all combinations of cells and their two direct neighbors in the top row and the resulting state in the bottom row. The top row is fixed, but the bottom row can be chosen freely, so there are \(2^8=256\) different elementary automata. We can assign a unique integer to each such automaton by interpreting the bottom row as a binary number. For instance, the bottom row of the cellular automaton that generates the Sierpiński triangle corresponds to the binary number \(00010110_2\), which is 22 in decimal; this rule is therefore called rule 22.
-
b) What is the number of the rule in part (a)?
-
c) Write a program that takes a rule as a number between 0 and 255 and simulates the corresponding cellular automaton by evolving a one-dimensional array of cells, returning a new array of cells. Use periodic boundary conditions.
-
d) Study the behavior of all 256 elementary cellular automata by creating images similar to the one in Fig. 5.8. Which rules generate interesting patterns?
Large Bit Sets
[5.16]In Section 5.4 we discussed how to represent sets of small integers using bits and how to perform elementary set operations using bit operations. In this exercise we will implement a class BitSet that uses arrays of integers to store and manipulate bit sets of arbitrary size.
An outline of the class we will implement is shown in Listing 5.10. There is a single field bits[] that holds the bit set itself. The size of the array determines the range of integers that can be stored in the data structure: An array of \(n\) long integers has \(64n\) bits and can therefore represent sets of integers in the range from 0 up to and including \(64n-1\). All methods that modify the bit set must enlarge the array if necessary.
Listing 5.10ch5 / BitSet
// A set of integers stored in an array of bits.
public class BitSet implements Iterable<Integer> {
    private long[] bits = new long[1];

    public BitSet() {}

    // ...
}
JDK: AbstractCollection, Integer
Let’s start with our first set of methods that handles access to individual elements of the set.
-
a) Implement an add() method that adds a number to the bit set by setting the corresponding bit to 1. The method must enlarge the bits[] array if necessary.
public boolean add(int value);
The return value of add() indicates whether the set was modified by the operation, in other words, it returns true if value wasn’t contained in the set before.
-
b) Implement contains() and remove().
public boolean contains(int value);
public boolean remove(int value);
The contains() method tests whether an integer is contained in the set, and remove() removes an integer from the set. How do you handle numbers that lie outside the range of the current bits[] array?
The default constructor in Listing 5.10 creates an empty set, but often it’s convenient to be able to initialize the set using either an existing bit set or an arbitrary collection of integers.
-
c) Implement the following two constructors:
public BitSet(BitSet other);
public BitSet(Collection<Integer> other);
Both constructors create a new bit set from a given set or collection of integers.
-
d) Implement equals() and hashCode().
public boolean equals(Object o);
public int hashCode();
The equals() and hashCode() methods should be implemented in such a way that any two BitSets that contain the same numbers are considered equal and have the same hash code.
-
e) Implement size() and isEmpty().
public int size();
public boolean isEmpty();
The size() method returns the number of elements in the bit set (that is, the population count of the bit pattern), and isEmpty() checks if the set is empty.
-
f) Implement the following four methods.
public boolean containsAll(BitSet other);
public boolean addAll(BitSet other);
public boolean removeAll(BitSet other);
public boolean retainAll(BitSet other);
The containsAll() method implements the subset relation \(\mathtt {this}\subseteq \mathtt {other}\) and returns true if all elements of this are also contained in other. The other three methods modify the elements of this based on the elements of other: addAll() adds all elements of other, effectively computing the set union \(S\cup T\); removeAll() removes all elements contained in other which corresponds to the set difference \(S-T\); and retainAll() removes all elements that are not contained in other which corresponds to the set intersection \(S\cap T\).
BitSet implements the Iterable interface, which makes it possible to iterate over the elements of the set. This interface requires that we implement a single method BitSet.iterator() that creates a new Iterator object, which can then be used to loop over the numbers stored in the set. The definition of iterator() looks as follows:2
// Iteration
public Iterator<Integer> iterator();
-
g) Design a class Iter that implements Iterator
and can be used to iterate over the elements of a BitSet. Implement BitSet.iterator(). Hint: Since the class needs access to the internal representation of BitSet, it should be defined as a nested class.
2 The Iterator interface is described in Appendix B.5.
Counting Bits
[5.17]The number of 1-bits in a bit sequence, often called its population count, is an important quantity that naturally occurs in many applications. The population count is simply the sideways sum of the binary digits; for example, the population count of \(11010111\) is \(1+1+0+1+0+1+1+1=6\). In this exercise we discuss a fast algorithm for computing the population count.3
To count the 1-bits in a number \(n\), we can use a divide-and-conquer algorithm that is similar to the recursive min function we discussed in Section 3.1: split \(n\) into to halves, count the bits in each half and then add the results. If we repeat this process recursively, splitting each sequence of bits into smaller and smaller parts, we are eventually left with the problem of computing the population count of a single bit, which is just the value of the bit itself. For example, to count the bits in 11010010, we first split it into two halves 1101 and 0010, then into groups of two bits, and finally into individual bits as shown in the left part of Fig. 5.9.
We then work our way up, counting the number of bits in each subtree by starting at the leaves and replacing each node with the sum of its two children. For the 2-bit groups, the population counts are 2, 1, 0, and 1; for the 4-bit groups \(2+1=3\) and \(0+1=1\), and for the original 8-bit number \(3+1=4\). This phase of the algorithm illustrated in the right part of Fig. 5.9.
By itself, this decomposition doesn’t buy us anything: To compute the population count of a \(B\)-bit integer, it still requires \(B-1\) additions, which is no better than iterating over the bits one by one. But there is a trick that lets us compute the numbers at each level of the tree in parallel. Consider the nodes just above the leaves, each of which holds the sum of of a pair of adjacent bits. We can compute these four sums in parallel by extracting the bits at odd positions and the bits at even positions, aligning the resulting bit patterns by shifting the bits at odd positions one place to the right, and then adding the bit patterns as if they were regular integers.
Let’s see how this works for \(n=11010010_2\). First we extract from the bit pattern of \(n\) the bits at even and the bits at odd positions and shift the odd bits one place to the right:
\(\seteqnumber{0}{5.}{9}\)\begin{align*} n \AND 01010101_2 &= 01010000_2 && \text {even bits}\\ (n \AND 10101010_2) \shr 1 &= 01000001_2 && \text {odd bits} \end{align*} Adding these two bit patterns yields
\(\seteqnumber{0}{5.}{9}\)\begin{align*} & 01010000_2\\ + & 01000001_2\\ = & 10010001_2. \end{align*} If we interpret the result as four 2-bit numbers, the result is \((10_2,01_2,00_2,01_2)\) or \((2, 1, 0, 1)\), which is the number of bits in the 2-bit groups of the original number \(n\). The whole computation can be implemented using just a few bit operations and one addition:
int n2 = (n & 0x55) + ((n >>> 1) & 0x55);
(By shifting n before extracting the bits at even positions, we can use the same bit mask 0x55 twice.) By adding even and odd bits in this way, we effectively perform four additions in parallel!
Each 2-bit block of n2 now contains a number between 0 and 2. Using almost the same trick again, we can sum all 2-bit blocks in parallel:
int n4 = (n2 & 0x33) + ((n2 >>> 2) & 0x33)
This extracts all 2-bit blocks at odd and even positions, aligns them, and adds them to produce two 4-bit numbers that again hold contain the number of bits in the corresponding region of the original number \(n\). Finally, we add the two resulting 4-bit numbers:
int n8 = (n & 0x0f) + ((n >>> 4) & 0x0f)
The variable n8 now holds the population count of the original number n.
Extend this scheme to compute the population count of a 64-bit integer and implement the resulting algorithm.
[5.18]There is an elegant algorithm for counting the number of trailing zero-bits in an integer that is based on the idea of binary search. Suppose we want to compute \(\text {ntz}(64, v)\), the number of trailing zeros in a 64-bit integer \(v\). If the lower 32 bits of \(v\) are all 0, we count the number of trailing zeros in the upper half of \(v\) and add \(32\); otherwise, we simply count the number of trailing zeros in the lower half of \(v\):
\(\seteqnumber{0}{5.}{9}\)\begin{equation*} \text {ntz}(64, v) = \begin{cases} 32+\text {ntz}(32, v \shr 32) & \text {if the lower 32~bits of $v$ are zero};\\ \text {ntz}(32, v) & \text {otherwise}. \end {cases} \end{equation*}
We can use the same idea to express \(\text {ntz}(32,v)\) in terms of \(\text {ntz}(16, v)\), and so on. Since every step halves the number of bits that must be inspected, computing the number of trailing zeros of an \(n\)-bit integer requires just \(O(\log _2 n)\) steps.
-
a) The base case of the recursive scheme sketched above is the function \(\text {ntz}(1, v)\), which computes the number of trailing zeros of a 1-bit number \(v\). How is this function defined?
-
b) Use this technique to implement a function countTrailingZeros() that computes the number of trailing zeros of a long integer. Hint: you can get rid of the recursion by rewriting code of the form
if (v & 0xffffffff != 0) {
    return 32 + ntz(32, v >>> 32);
} else {
    return ntz(32, v);
}
as
int count = 0;
if (v & 0xffffffff != 0) {
    count += 32;
    v >>>= 32;
}
return count + ntz(32, v);
-
c) Use the same idea to define a function \(\text {nlz}(64, v)\) that computes the number of leading zeros of a 64-bit integer \(v\), that is, the number of zeros to the left of the most significant 1-bit.
-
d) Implement a function that computes the number of leading zeros. Can you find a trick to get rid of the recursion?
3 In practice, the fastest way to compute the population count is usually the bitCount() function defined in Long and Integer, which uses hardware instructions if available.
5.7 Chapter Notes
In this chapter we have discussed how store data in bits and groups of bits and how to implement algorithms that operate on those bits. Programming techniques for working with bits are sometimes referred to as bit tricks, and they are particularly useful in programs that process large amounts of data or that have to work within tight time and memory constraints. Bit tricks are one of the hallmarks of systems programming, the branch of programming that deals with low-level and resource-constrained problems. A good introduction to this subject is the book by Bryant and O’Hallaron [22].
A popular collection of bit tricks that are useful in low-level programming tasks is maintained by Sean Anderson at https://graphics.stanford.edu/~seander/bithacks.html. The ultimate reference on bit tricks and related low-level programming techniques is Hacker’s Delight [94]. It’s a dense, technical book primarily written for low-level programmers, but it contains a wealth of material that is hard to find elsewhere. The use of bitwise operations in the context of combinatorial and arithmetic problems is discussed in Volume 4A of The Art of Computer Programming [61].
Bitmap images were widely used in the earlier days of computing and computer graphics, not only due to their compact representation in memory but also because bitwise operations made it possible to operate on multiple pixels at once. The digits we used for our bitmap font in Fig. 5.1 come from the SNES game Chrono Trigger and were used in a few other Japanese RPGs released during the 1990s. The font’s design was heavily inspired by a font called Chicago that was designed by Susan Kare for the Apple Macintosh:
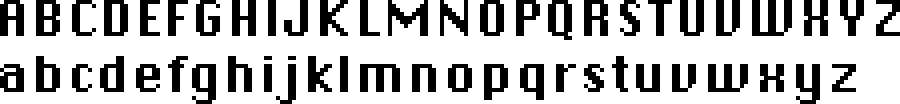
Another well-known bitmap font was (and still is) used on IBM PCs: